Leadership in Biotech

Category: AI ∩ Bio Page 1 of 3

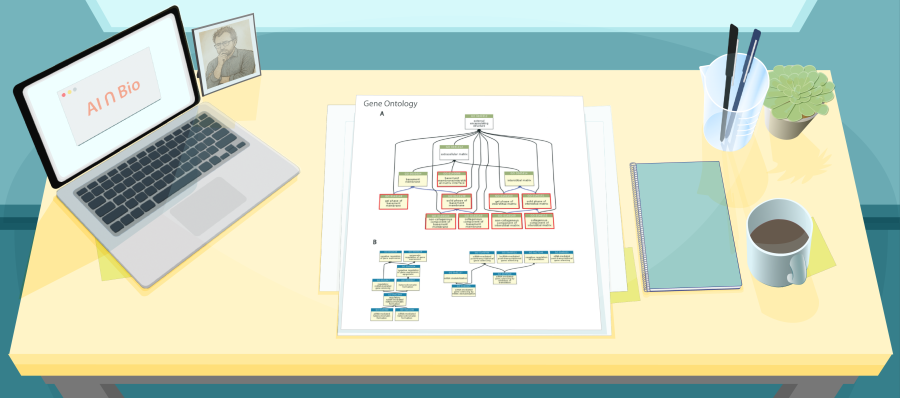
Illustration of a desk with a figure from a recent paper about GeneOntology

The Gene Ontology Knowledgebase in 2026

This year’s Gene Ontology (GO) update is a reminder that infrastructure choices shape scientific conclusions, getting to the heart of this foundational tool for understanding biology at a time when omics, enrichment analyses, and AI models increasingly rely on GO as biological “ground truth.”

Are you new to Gene Ontology? See the PDF for a deeper dive.

What actually changed (2022–2025)

A few highlights that matter in practice:

  • Major ontology cleanup: hundreds of new terms added, thousands of imprecise or redundant terms obsoleted.
  • Human Functionome v2.0: a reviewed, integrated annotation set now covering ~84% of human genes, reducing enrichment clutter while preserving biological relevance.
  • GO-CAMs scaled up: >1,500 expert-curated causal pathway models linking gene activities with evidence, moving beyond flat gene lists toward mechanistic flow.

Why this paper matters for diagnostics, AI, and innovation leaders
GO and AI models share something important: both are compressions of complex biology.

  • Gene Ontology is a structured compression of current biological knowledge, but lack explicit biological context.
  • Genomic language models are statistical compressions of high-dimensional data, but lack biological grounding.
  • GO provides a curated prior (a biological sanity check) but it abstracts away context (cell state, disease, rewiring). In cancer, that context is often the signal. Used well, GO disciplines thinking and prevents nonsense. Used naively, it produces answers that look rigorous, but are nonsensical.
  • The opposite risk exists with genomic language models. They learn dense embeddings that can capture patterns not explicitly labeled, but the derived “understanding” is not mechanistic by default; it’s statistical compression. And they can overindex on historical data distributions, which can amplify biases.

An intriguing option (and a common one in many recent AI Bio papers), is to combine Gene Ontology with language models.

For example:
Language model → propose;
Gene Ontology → check.

Use a language model to propose functional/interaction hypotheses from data & Gene Ontology to flag things like contradictions and flag known process vs believable novelty vs likely nonsense.

A note to early-career scientists

Impact doesn’t only come from novelty. It comes from:

  • caring about definitions and evidence,
  • understanding the assumptions baked into your tools,
  • and knowing where structure helps, and where it hides uncertainty.

Bridge discovery with discipline, and insight with infrastructure, and you’ll do work that lasts.

Skip to PDF content
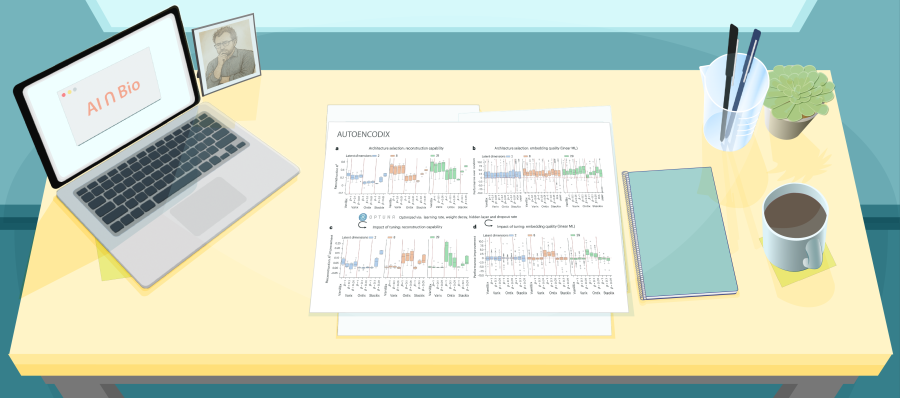
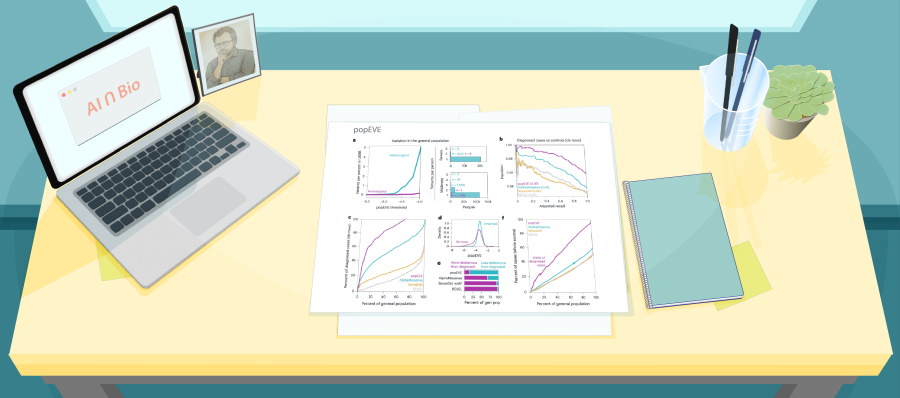
Illustration of a desk with a figure from a recent paper about AUTOENCODIX

Interpretable Latent Spaces, Messy Biology: What AUTOENCODIX Teaches Us About Autoencoders in the Wild

This week in AI ∩ Bio I dug into AUTOENCODIX, an open-source framework that stress-tests autoencoders (AEs) on real multi-omics data.

The punchline: no single architecture wins, reconstruction scores can mislead, and “interpretable” latent spaces inherit every bias baked into our ontologies. This paper provides exactly the kind of clarity we need to effectively apply these models in diagnostics and biomarker discovery.

AUTOENCODIX is a new open-source framework that tries to bring order to the AEs chaos in multi-omics, allowing the user to test multiple AEs through the same pipeline, then compare not just loss curves but how useful the learned embeddings actually are for biology and prognosis. (AEs explained in carousel)

Scientifically, a few themes stood out:

  1. they show how tuning β in VAEs affects performance; low β favors reconstruction; high β imposes compact, disentangled latent spaces.
  2. across TCGA and single-cell cortex data, no AE architecture consistently outperforms others. Good reconstruction doesn’t guarantee useful embeddings. Ontix, the biologically structured AE, wires decoder layers to known pathways or chromosomes, making latent dimensions interpretable. But robustness varies and depends on learning rate; and the results hint at artifactual learning (see comments).

Diagnostics-leadership perspective

This paper is a reminder to separate infrastructure from insight.

AUTOENCODIX is essentially AE infrastructure: it standardizes data handling, model training, and evaluation so you can ask disciplined questions instead of chasing whichever architecture is trending.

The results also challenge the reflex to equate fancier models with better clinical value: PCA remains a very strong baseline, and ontology-based models only shine when the chosen ontology matches the question and is treated carefully as a potential source of bias, not ground truth.

For leaders deciding where to invest, the take-home is: fund frameworks that make comparisons fair and reproducible, and judge models by task-relevant endpoints and robustness across cohorts—not by reconstruction loss or aesthetic latent plots.

For early-career scientists

There’s a quieter lesson here about how to work with powerful tools without giving up your scientific spine.

The authors don’t present a magical autoencoder that “solves” multi-omics; instead, they map trade-offs, show when tuning helps and when it doesn’t, and surface uncomfortable findings like decreased robustness after hyperparameter optimization for ontology-based VAEs.

If you’re building a career in computational or experimental biology, papers like this are an invitation to open the hood: run the benchmarks, break the assumptions, test models on tasks you actually care about, and treat interpretability as something you design and stress-test—not something you assume.

Skip to PDF content
Illustration of a desk with a figure from a recent paper about popEVE

From Evolutionary Intolerance to Clinical Insight: What popEVE Teaches Us About Missense Variants

This week in AI ∩ Bio, we look at “Proteome-wide model for human disease genetics”, which introduces popEVE, an unsupervised model for prioritizing missense variants across the human proteome.

The key idea: give each amino-acid change a calibrated severity score based on how evolutionarily and statistically “intolerant” it looks, without pretending to directly predict pathogenicity. But even though the model is not trained on pathogenicity, the scores it produces are correlated with pathogenicity, and often clustered in biologically plausible regions.

Scientific Insight

popEVE combines two sequence-based models (EVE and ESM-1v) with real-world human variation from ~460,000 genomes (UK Biobank + gnomAD).

EVE and ESM-1v together give a composite view of how “acceptable” a variant is:

  • EVE is a variational autoencoder trained on multiple sequence alignments (MSAs) across species. It captures deep evolutionary conservation
  • ESM is a large-scale unsupervised transformer model trained on unlabeled protein sequences. It captures local structural and biophysical coherence

They are combined (with some weighting) into a raw deleteriousness score per variant.

Then, they look at Human Variant Depletion: Presence/Absence in gnomAD/UKBB, which provides empirical evidence of human constraint.

For each protein position, they ask:
“Across 460,000 people, how many unique missense variants were observed here?”

If a position has:

  • Many unique variants → assumed tolerant in humans
  • Few or no variants → suggests purifying selection, i.e., likely deleterious if mutated

They feed this site-level variant density into a Gaussian Process calibration layer, which:

  1. Adjusts the EVE+ESM score to reflect gene-specific constraint
  2. Produces a calibrated score that is comparable across genes

The resulting score correlates with disease severity and clusters in known functional domains and interfaces, and in singleton diagnostic cases, ~80% of truly causal variants land in the model’s top 10 candidates.

Importantly, the authors are clear about limits: no non-coding variants, no epistasis or tissue context, and potential confounding from sequencing and coverage artifacts.

Leadership Angle

For diagnostics leaders, popEVE is a tool for smarter triage, not a final verdict.

It offers a transparent, cross-gene notion of constraint that can sharpen variant review in rare disease and carrier screening workflows, if we remember exactly what it measures: statistical intolerance, not clinical truth.

Mentorship Angle

For early-career scientists, this paper demonstrates disciplined scope and thoughtful integration.

The authors explicitly state what popEVE does not do, then show where its scores line up with known biology and clinical patterns.

If you’re building a career in biotech, this is the sweet spot: models that are powerful because you understand the biology, the data generation, and the limits of what any score can tell you about a real patient.

Skip to PDF content
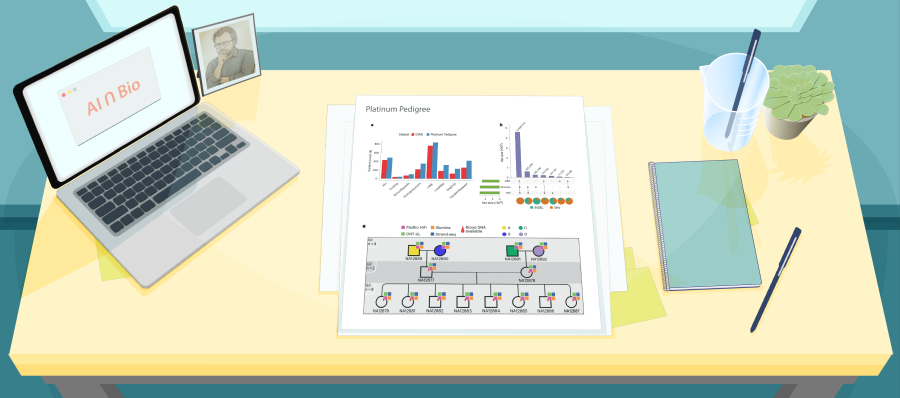
Illustration of a desk with a figure from a recent paper about Platinum Pedigree

AI Models Need Better Truth—Platinum Pedigree Shows How

When I was in high school, I was obsessed with genetics. The Human Genome Project was in full swing, and it felt like the future was being written in real time. I told a family friend I wanted to become a geneticist. He smiled and said, “My cousin is at the NIH. They’ll finish the human genome before you finish college, so I wouldn’t bother.”

The project wrapped in 2003. But papers like this remind me how wrong that prediction was. Even after “finishing” the genome, we’re still uncovering what accuracy, completeness, and truth really mean.

The new Platinum Pedigree study pushes that frontier again.

Scientific Insight

This work builds one of the most comprehensive germline variant benchmarks to date, deep long-read sequencing across a 10-member family, combined with Mendelian logic.

By integrating PacBio HiFi, Oxford Nanopore Technologies, and Illumina and testing every variant against inheritance patterns, the authors defined 2.77 Gb of high-confidence genome (~200 Mb beyond prior benchmarks), including repeats, segmental duplications, and low-mappability regions.

The key innovation is biological grounding.

Each child inherits one haplotype from each parent; variants that obey those segregation patterns are kept, and those that don’t are removed. This yielded ~4.7M SNVs, 768k indels, 537k tandem repeats, and 24k structural variants as pedigree-consistent truth.

When DeepVariant was retrained on this truth set, error rates dropped by ~34% across challenging classes, especially indels and tandem repeats.

Better labels → better models.

Leadership Angle

For diagnostics leaders, this signals where the field is heading: stronger evidence standards, clearer definitions of “truth,” and biologically informed benchmarks rather than technology-constrained heuristics.

This strategy of combining multiple sequencing technologies and adjudicating discrepancies with inheritance is exactly how robust systems are built in uncertain environments.

It mirrors what clinical diagnostics now requires: pipelines that perform not just in easy regions, but in messy, clinically meaningful ones.

And it underscores a central lesson in AI-enabled diagnostics: your model is only as good as the ground truth you train it on.

The regions that are currently messy and difficult to map: that’s where new breakthroughs in understanding will occur.

Mentorship Angle

For early-career scientists, the lesson is craftsmanship. This paper doesn’t debut a flashy algorithm; it elevates the foundations. It asks simple but profound questions: Did this variant follow the rules of inheritance? If not, are we sure it’s real?

Your technical tools matter, but your willingness to interrogate assumptions matters more. If you want to build a meaningful career in genetics in this age of AI, stay curious about the scaffolding beneath the science.

Breakthroughs often start there.

Skip to PDF content
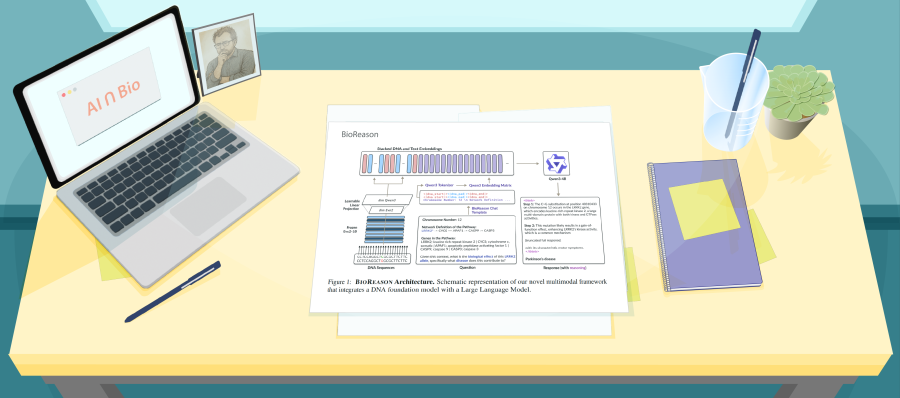
Illustration of a desk with a figure from a recent paper about BIOREASON

From Prediction to Explanation: How BIOREASON Reframes Genomic AI as a Reasoning Problem

While DNA foundation models like Evo2 and Nucleotide Transformer can encode genomic sequences into dense, information-rich embeddings, they still operate as black boxes—excellent at prediction, poor at explaining why. Large language models offer the opposite tradeoff: they excel at generating explanations but treat DNA as unstructured text, without any built-in understanding of motifs, regulatory grammar, or sequence constraints.

What BIOREASON Does

BIOREASON introduces a multimodal architecture that fuses:

  • A frozen DNA foundation model to encode biological sequence semantics
  • A fine-tuned LLM that ingests both the embeddings and natural-language context

This pairing enables:

  • Natural-language reasoning grounded (at least in theory) in genomic content
  • Generation of interpretable, mechanistic chains (variant → pathway → phenotype)
  • Improved predictive performance relative to either the DNA FM or LLM alone

But what do DNA embeddings “mean”?

Short answer: we don’t know—and that uncertainty is inherent to foundation models.

  • These embeddings are latent representations learned through massive unsupervised training.
  • They’re presumed to encode motifs, conservation, splicing signals, or regulatory cues because the model needed those features to solve its training task.
  • They are not human-interpretable.

BIOREASON treats these embeddings as a kind of “biological fingerprint,” trusting that an LLM can learn to reason over them with enough supervised examples. The gamble is that:

  • The DNA model has learned useful biological grammar
  • The LLM can exploit those learned signals to answer new questions

But there’s no explicit decoding or truth-checking of what the embeddings represent internally.

Why reasoning faithfulness still isn’t guaranteed

The <think> traces produced by BIOREASON are not probabilistic, validated, or causally guaranteed. The model “believes” its chain, but you must judge its soundness.

Anthropic’s “Reasoning Models Don’t Always Say What They Think” (Chen et al., 2025) shows why this matters: reasoning-tuned models often rely on subtle internal shortcuts, then fail to verbalize them, generating fluent but misleading explanations. BIOREASON inherits the same risk.

Key concerns:

  • Explainability ≠ faithfulness
    A coherent chain does not mean the model followed that chain internally.
  • Potential post-hoc rationalization
    The model may rely on correlations or dataset artifacts, then wrap them in a plausible narrative.
  • Compromised auditability
    If the chain isn’t faithful, transparency becomes performative rather than informative.
  • Hidden biases or shortcut features
    The model might use annotation frequency, ClinVar priors, or pathway prevalence without ever stating so.
  • Lack of mechanistic grounding
    True mechanistic understanding would require identifying which embedding dimensions or sequence contexts drove the decision. The <think> chain alone cannot provide this.

Let’s step back: What’s genuinely novel here?

Despite its limitations, BIOREASON introduces several meaningful advances for the field.

Fusion of Biological Foundation Models with Language Reasoning

Traditional models split into two camps:

  • Models that understand sequence biology (Enformer, Evo2, Nucleotide Transformer)
  • Models that generate explanations (GPT-style LLMs)

BIOREASON bridges these worlds:

  • Anchors reasoning in sequence-aware embeddings
  • Trains the LLM to produce structured, biologically grounded explanations

Why this matters

It reframes variant interpretation as causal narrative inference—a closer match to how human scientists reason.

Structured Explainability via <think> Tokens

Most genomics tools output scores or saliency maps. BIOREASON outputs reasoning.

  • <think> traces formalize a stepwise, human-auditable chain
  • Explanation becomes part of the training objective, not a reverse-engineered artifact

Why this matters

This is one of the first genomics models to explicitly train for mechanistic-style explanation.

A Real Multimodal Interface for Genomics

Multimodal architectures (image+text, audio+text) are flourishing, but genomics has lagged.

BIOREASON shows:

  • DNA sequences can be treated as semantic inputs
  • LLMs can generate biologically coherent outputs when grounded in embeddings

Why this matters

It opens the door to models that integrate DNA, RNA, protein, expression, and literature signals—moving us nearer to true AI lab partners.

Raises Critical Questions About Faithfulness

By making reasoning visible, BIOREASON forces the field to confront fundamental issues:

  • What does it mean for a model to “understand” a variant?
  • How do we measure explanation fidelity, not just fluency?
  • How can we prove the model’s logic is driven by sequence rather than language priors?

Why this matters

These questions will shape the evaluation standards for biological AI over the next decade.

Final Thought

BIOREASON’s contribution isn’t that it solves variant interpretation. It’s that it reframes the problem as reasoning, not classification. It pushes us closer to models that narrate mechanistic hypotheses—but it also reminds us why faithfulness, causal testing, and biological grounding matter just as much as model performance.

With stronger embeddings, uncertainty calibration, perturbation tests, and wet-lab validation, this line of work could become a cornerstone of how AI collaborates with scientists in the years ahead.

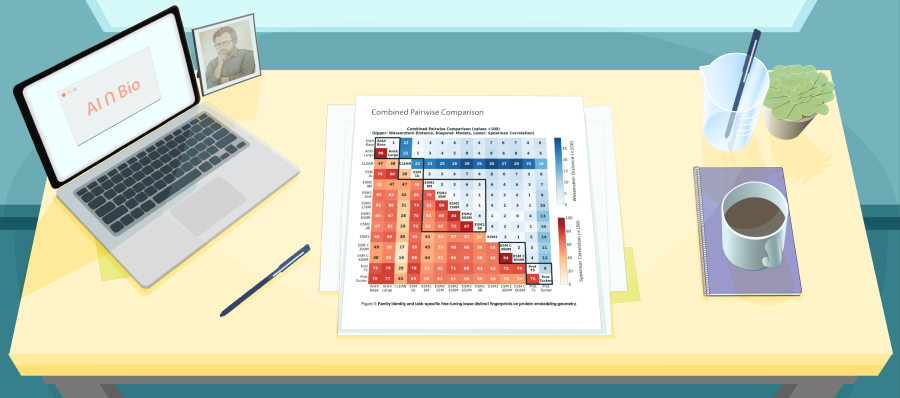
Illustration of a desk with a figure from a recent paper about the pLM

From Embeddings to Insight

Protein language models (pLMs) learn from raw amino-acid sequences and turn each protein into a numerical “embedding.” Unlike AlphaFold (which is trained to predict 3D structure), pLMs are trained only on sequence patterns, then reused for tasks like fast homology search, function hinting, or variant triage.

The appeal of pLMs is that they might:

  • Identify remote homology
  • Assist in function annotation, especially for uncharacterized proteins
  • Predict mutation effects
  • Serve as general-purpose inputs for fold prediction, domain classification, etc.

This study benchmarks 14 pLMs to evaluate how well they capture biological similarity along three axes:

  • Sequence
  • Structure
  • Function

For each axis, the authors compare distances between embeddings to a “ground truth” similarity metric (see below). They test whether models reflect these similarities in two ways:

  • Inherent information: Does the raw embedding distance between two proteins correlate with their similarity?
  • Extractable information: Can a small model trained on the embeddings predict the similarity score?

Scientific Insight

This paper provides a systematic, well-designed benchmark for protein language models, useful for those developing or deploying these models computationally.

But it defines “success” in terms of alignment with thorny labels, which is a limitation of the field at the moment. See PDF below.

With that caveat, the results are compelling:

Out-of-the-box, small models often perform as well as large ones.

  • “Size-performance paradox”: model size doesn’t guarantee better embedding quality for biological similarity.

Larger models encode more information, but it’s hidden.

  • You need to train a model on the embeddings to “extract” biological signal.

Task-specific models don’t generalize.

  • Fine-tuning a model for one problem (e.g., enzyme function) distorts the embedding space and reduces general usefulness.

Leadership Angle

Bigger isn’t automatically better (we’re seeing this with genomic models as well). But also be mindful of what you are benchmarking to, and its relevance to what you care about.

Mentorship Angle

Let pLMs speed the front end of discovery, then make the science real.

  • Start with a testable claim in plain language—e.g., “Nearest neighbors in embedding space enrich for shared catalytic residues better than a sequence-identity cutoff at the same recall.”
  • Pre-register thresholds; include hard negatives (same fold, different function; low identity, same mechanism) & use controls (shuffle labels, etc)
  • Report where it fails—disordered regions, multi-domain proteins, complexes, and say why you think it failed
  • Document assumptions (databases, structure confidence, training leakage)

The win isn’t a pretty plot; the win is turning speed into better experiments that change what you do at the bench.

Skip to PDF content
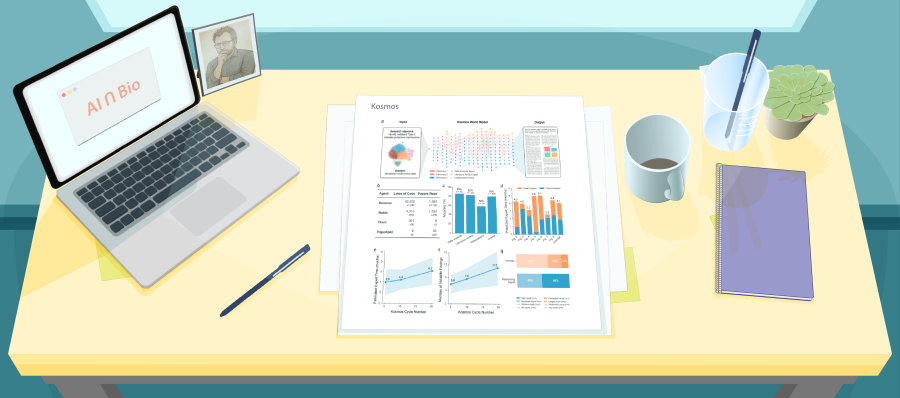
Illustration of a desk with a figure from a recent paper about the Kosmos AI agent

Kosmos and the Culture of Discovery

AI Scientists are all the rage these days, and that excitement ramped up a notch or ten this week with the announcements of the Kosmos preprint from prominent AI researchers (notably, FutureHouse). The Kosmos system takes on an ambitious question:

Can an AI not only assist with science, but do science on its own?

Designed to read literature, analyze data, and generate new hypotheses in 12-hour autonomous runs, Kosmos reports nearly 80% statement accuracy and the equivalent of six months of human research per cycle.

It’s an extraordinary technical achievement…

…and…

…one that forces us to ask what, exactly, counts as scientific discovery?

Scientific Insight

At its core, Kosmos is a multi-agent system. One agent searches the literature, another analyzes data, and a coordinating model stitches their findings together into a cohesive research narrative.

The architecture is impressive and elegant, but it also reveals a key limitation.

Kosmos optimizes for coherence—for ideas that fit neatly together—rather than for falsifiability or experimental test.

The result is a system that can produce consistent and compelling stories, but not yet the self-correcting friction that turns a story into durable scientific insight.

Leadership Angle

For those of us leading R&D organizations, Kosmos is both inspiring and instructive. It shows how far autonomous reasoning has come. And it also demonstrates how easily coherence can masquerade as progress.

In the context of industrial scientific research, this lesson feels particularly relevant. Our job isn’t to chase automation for its own sake (although driving down cost is certainly a constant imperative), it’s to develop products that are safe, effective, and hold up in the real world.

To accomplish this task, we need to design scientific teams where human judgment and machine synthesis elevate the best of what each brings to the table.

Our new AI teammate is here, and in order to figure out how to integrate them safely and effectively with your human team, learning to manage them effectively is absolutely critical.

Mentorship Angle

For early-career scientists, Kosmos highlights part of what the future of science will look like, so pay attention to what these AI ‘scientists’ can and cannot deliver, and how they evolve.

Right now, Kosmos is fast, thorough, and tireless, but optimized to find coherence. The craft of science still lives in that space of productive stupidity and intellectual humility: the messy, uncertain, human part where you argue with data (and with your fellow scientists), question assumptions, and let yourself be wrong. AI can’t automate that part (at least not yet).

If Kosmos points to a future of machine collaborators, then the most valuable skill you can build now is learning how to think with them—and sometimes, against them.

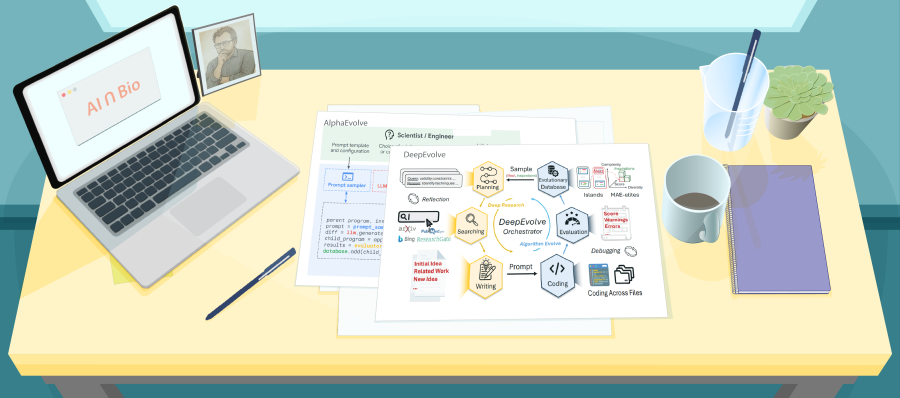
Illustration of a desk with figures from recent papers about DeepEvolve and AlphaEvolve

From AlphaEvolve to DeepEvolve: What We’re Learning About Machine-Led Scientific Discovery

Over the past year, AlphaEvolve (DeepMind) and DeepEvolve (Liu et al.) have taken on one of science’s most audacious challenges: can machines not only execute discovery but originate it? Both leverage large language models (LLMs) to iteratively evolve algorithms through feedback and automated evaluation.

AlphaEvolve reframed discovery as code evolution: LLMs proposing edits, testing them, and optimizing against performance scores. DeepEvolve extends this paradigm by integrating deep research: literature retrieval, structured reasoning, multi-file implementation, and automatic debugging. Together, they signal a shift from code-writing tools to more active scientific collaborators and raise foundational questions about what counts as “understanding.”

Scientific Insight

AlphaEvolve’s achievements are real and impressive: it discovered a novel algorithm for 4×4 matrix multiplication, improving on a benchmark that had stood since 1969. But its limitations are equally instructive. When optimization is tethered entirely to scalar reward signals, models risk learning how to perform rather than how to understand.

DeepEvolve addresses some of this by incorporating retrieval-augmented reasoning and grounded iteration, showing measurable gains across nine domains—from molecular property prediction to polymer engineering. Yet the deeper challenge persists: these systems can refine heuristics, but they cannot yet articulate principles; the boundary between discovery and reward chasing remains unresolved.

Leadership Angle

For R&D leaders in life sciences or diagnostics, these systems are both technical achievements and strategic case studies.

Peter Drucker once warned: “What gets measured gets managed—even when it’s pointless to measure or manage it.” In the context of these papers, the risk is clear: if we measure only performance, we may optimize into blind alleys. The opportunity lies in designing systems (and organizations!) that ask better questions, not just produce better scores.

Mentorship Angle

For early-career scientists, the message isn’t to fear or avoid these tools (please don’t, these tools are amazing!), but to understand their limitations. AlphaEvolve and DeepEvolve can automate exploration, but perhaps not judgment. They can generate thousands of hypotheses in hours, but still depend on human insight to distinguish signal from noise. And require careful thought in setting up reward systems that uncover real meaning in the context you care about.

In a world where even machines can “research,” the defining trait of good science will be the discipline to ask whether improvement is meaningful, not just measurable. That’s the work of real discovery and no algorithm can evolve that for us (at least not yet!).

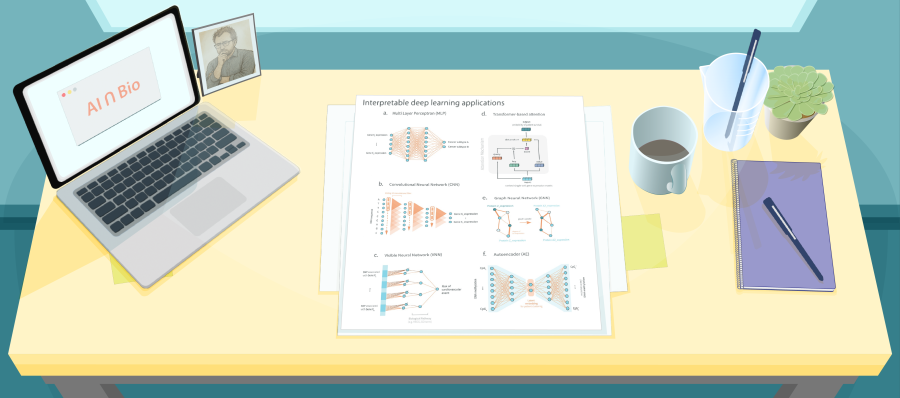
Illustration of a desk with a figure from a recent paper about interpretable deep learning applications

Toward Mechanism-Centric Interpretability in Genomic Machine Learning

Rather than reviewing a paper, this week’s post takes a broader view on where we are at with respect to interpretability in genomics ML models.

As the field continues to rigorously interrogate the most recent ML genomics models, it has become clear that it’s incredibly easy to fool ourselves about what these models are learning, what they can predict, and how to do better.

One component of improving on the current state is to get more serious about interpretability. Most interpretability efforts remain retrospective—feature rankings, attention maps, or gradient plots that rationalize outputs but rarely reveal how, or whether, the model’s reasoning aligns with biology.

If we care about mechanism (and we should, because this is how models become more extensible and useful), we need a shift in stance. Interpretability should not be a gloss applied at the end of analysis, it should be part of how models are built, tested, and revised.

Here I posit that there are four questions worth asking of every architecture and dataset to help us move in that direction.

What are we interpreting: mechanisms, predictions, or confounds?

Each target demands a different standard of evidence. Mechanistic interpretability seeks causal structure; predictive interpretability seeks justification; artifact detection seeks bias. Without distinguishing them, we risk mistaking coherence for truth.

What biological hypotheses are encoded in the model architecture?

Every design choice carries an implicit worldview: MLPs flatten dependencies; GNNs canonize known graphs; transformers elevate context as signal. These are not neutral—they shape what the model is capable of discovering, and what it will systematically miss.

Can multimodal data be used to falsify interpretations?

Adding data layers isn’t just about increasing modeling power. Done correctly, an additional modality can act to challenge the others, serving as an independent test of whether the model’s inferences hold up under a different lens.

How can interpretability inform model iteration?

Used well, interpretability is diagnostic. It surfaces blind spots: missing biological priors, unrepresentable hierarchies, or architectural constraints that obscure mechanism. Those failures are invitations to refine both model and experiment.

Why it matters

Interpretability is not a transparency feature; it’s a scientific claim about correspondence between computation and biology.
And like any scientific claim, it must be testable, falsifiable, and revised in light of evidence.

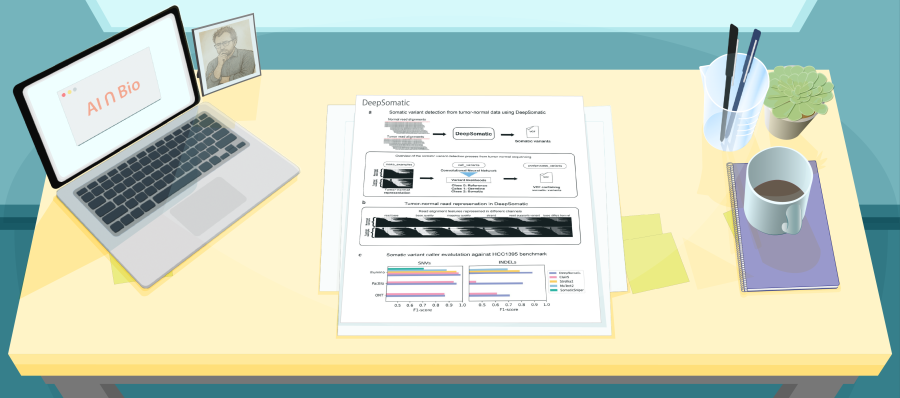
Illustration of a desk with a figure from a recent paper about DeepSomatic

DeepSomatic and the question of how AI learns from itself

DeepSomatic, published this month in Nature Biotechnology, represents a milestone for cancer genomics: a deep-learning method that detects somatic small variants across both short- and long-read sequencing data. Built on Google’s DeepVariant framework, it bridges Illumina, PacBio HiFi, and Oxford Nanopore datasets and introduces CASTLE, a new multi-platform benchmark of six tumor–normal cell lines made openly available to the community. For anyone working in precision oncology, the technical ambition here is remarkable: one model spanning technologies, sample types, and variant classes.

Scientific Insight

DeepSomatic converts paired tumor–normal reads into tensor “images” that feed a convolutional neural network capable of distinguishing somatic, germline, and reference variants. The model outperformed leading tools such as Strelka2 and ClairS across variant types and variant allele frequencies, and it maintained accuracy across multiple sequencing chemistries. Beyond its raw performance, the CASTLE dataset fills a major gap in the field: creating a real benchmark for long-read somatic variant detection where none previously existed.

Scientific Rigor Note

Like many GenAI systems, DeepSomatic may fall pray to non-obvious data leakage, and would benefit from more explainability. Some of its evaluation data overlap with the model’s own training inputs, raising the risk of circular benchmarking bias, and the study offers little insight into why the network makes its calls.

Leadership & Mentorship Reflection

Building trustworthy AI in medicine requires independent data, transparent reasoning, and humility about limitations that are baked into how these models work.

For early-career scientists, this paper is a case study in responsible ambition: innovate boldly, share your data openly, and interrogate your own benchmarks. AI or not, progress comes from rigorous, open science that understands its own limitations.

Page 1 of 3

Powered by WordPress & Theme by Anders Norén