
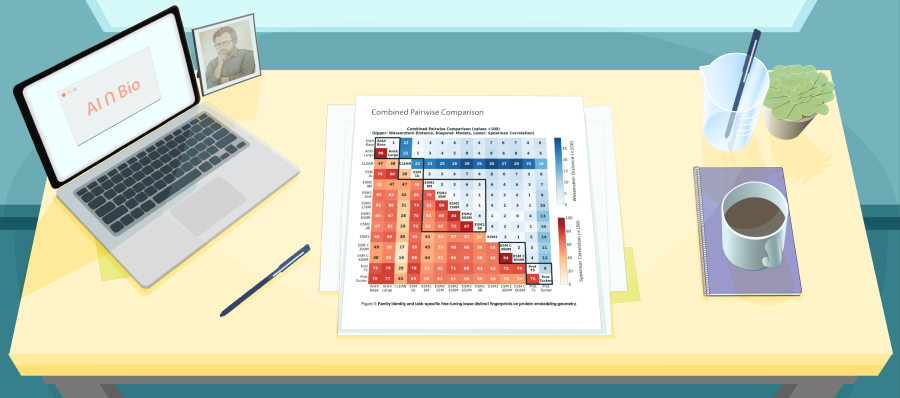
Protein language models (pLMs) learn from raw amino-acid sequences and turn each protein into a numerical “embedding.” Unlike AlphaFold (which is trained to predict 3D structure), pLMs are trained only on sequence patterns, then reused for tasks like fast homology search, function hinting, or variant triage.
The appeal of pLMs is that they might:
- Identify remote homology
- Assist in function annotation, especially for uncharacterized proteins
- Predict mutation effects
- Serve as general-purpose inputs for fold prediction, domain classification, etc.
This study benchmarks 14 pLMs to evaluate how well they capture biological similarity along three axes:
- Sequence
- Structure
- Function
For each axis, the authors compare distances between embeddings to a “ground truth” similarity metric (see below). They test whether models reflect these similarities in two ways:
- Inherent information: Does the raw embedding distance between two proteins correlate with their similarity?
- Extractable information: Can a small model trained on the embeddings predict the similarity score?
Scientific Insight
This paper provides a systematic, well-designed benchmark for protein language models, useful for those developing or deploying these models computationally.
But it defines “success” in terms of alignment with thorny labels, which is a limitation of the field at the moment. See PDF below.
With that caveat, the results are compelling:
Out-of-the-box, small models often perform as well as large ones.
- “Size-performance paradox”: model size doesn’t guarantee better embedding quality for biological similarity.
Larger models encode more information, but it’s hidden.
- You need to train a model on the embeddings to “extract” biological signal.
Task-specific models don’t generalize.
- Fine-tuning a model for one problem (e.g., enzyme function) distorts the embedding space and reduces general usefulness.
Leadership Angle
Bigger isn’t automatically better (we’re seeing this with genomic models as well). But also be mindful of what you are benchmarking to, and its relevance to what you care about.

Mentorship Angle
Let pLMs speed the front end of discovery, then make the science real.
- Start with a testable claim in plain language—e.g., “Nearest neighbors in embedding space enrich for shared catalytic residues better than a sequence-identity cutoff at the same recall.”
- Pre-register thresholds; include hard negatives (same fold, different function; low identity, same mechanism) & use controls (shuffle labels, etc)
- Report where it fails—disordered regions, multi-domain proteins, complexes, and say why you think it failed
- Document assumptions (databases, structure confidence, training leakage)
The win isn’t a pretty plot; the win is turning speed into better experiments that change what you do at the bench.
Skip to PDF content