
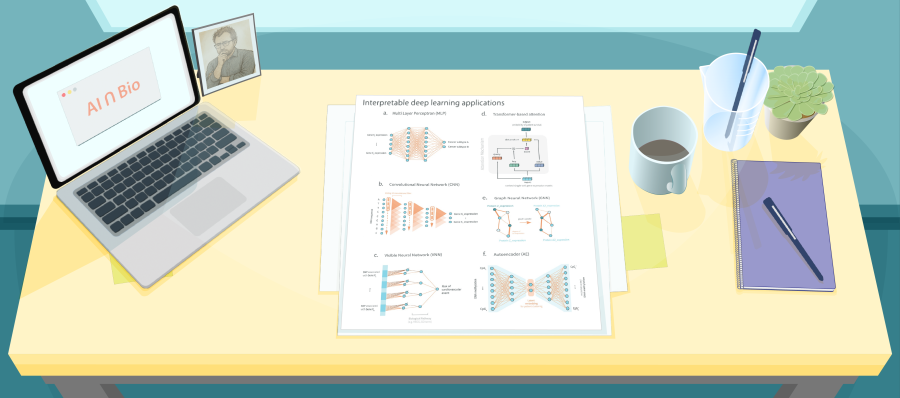
Rather than reviewing a paper, this week’s post takes a broader view on where we are at with respect to interpretability in genomics ML models.
As the field continues to rigorously interrogate the most recent ML genomics models, it has become clear that it’s incredibly easy to fool ourselves about what these models are learning, what they can predict, and how to do better.
One component of improving on the current state is to get more serious about interpretability. Most interpretability efforts remain retrospective—feature rankings, attention maps, or gradient plots that rationalize outputs but rarely reveal how, or whether, the model’s reasoning aligns with biology.
If we care about mechanism (and we should, because this is how models become more extensible and useful), we need a shift in stance. Interpretability should not be a gloss applied at the end of analysis, it should be part of how models are built, tested, and revised.
Here I posit that there are four questions worth asking of every architecture and dataset to help us move in that direction.
What are we interpreting: mechanisms, predictions, or confounds?
Each target demands a different standard of evidence. Mechanistic interpretability seeks causal structure; predictive interpretability seeks justification; artifact detection seeks bias. Without distinguishing them, we risk mistaking coherence for truth.
What biological hypotheses are encoded in the model architecture?
Every design choice carries an implicit worldview: MLPs flatten dependencies; GNNs canonize known graphs; transformers elevate context as signal. These are not neutral—they shape what the model is capable of discovering, and what it will systematically miss.
Can multimodal data be used to falsify interpretations?
Adding data layers isn’t just about increasing modeling power. Done correctly, an additional modality can act to challenge the others, serving as an independent test of whether the model’s inferences hold up under a different lens.
How can interpretability inform model iteration?
Used well, interpretability is diagnostic. It surfaces blind spots: missing biological priors, unrepresentable hierarchies, or architectural constraints that obscure mechanism. Those failures are invitations to refine both model and experiment.

Why it matters
Interpretability is not a transparency feature; it’s a scientific claim about correspondence between computation and biology.
And like any scientific claim, it must be testable, falsifiable, and revised in light of evidence.