
Leadership in Biotech

Tag: GPT

Illustration of a desk with a figure from a recent paper about AI interpretability in biology

What Are Genomic Transformers Actually Learning?

This week’s AI ∩ Bio: Reading the Revolution post explores a new paper tackling one of the biggest challenges in AI for biology: interpretability.

Specifically, how can we tell what genomic transformer models are learning and whether those internal patterns map to real biological concepts?

The study proposes a systematic framework to analyze attention heads in models like DNABERT and scGPT. It reveals that many attention heads naturally align with key biological features—such as transcription start sites, sequence motifs (e.g., TATAAA), GC content, conservation scores, and Gene Ontology categories like “neuron projection” or “mitochondrial membrane.” This interpretability emerges even during self-supervised pre-training and strengthens with task-specific fine-tuning.

Key Findings

  • Attention heads develop strong correlations with biologically meaningful features.
  • These heads tend to be more important for predictive performance, as shown by ablation experiments.
  • Interpretability is shaped by tokenization strategy (e.g., overlapping vs. non-overlapping k-mers).
  • GPT-4 was used to generate descriptive summaries of head activity (e.g., “TATA box detector”)—but these require validation, as they can miss label-specific nuance.

Limitations

  • Correlation ≠ causation: attention may highlight a feature without depending on it for prediction.
  • Current analyses treat attention heads in isolation—without clustering or organizing them into higher-level “concept modules.”
  • GPT-4 summaries, while useful, may overgeneralize or obscure context-dependent patterns.

Why This Matters

This work moves the field closer to a compelling vision: transformer models that don’t just output predictions, but expose interpretable biological patterns that scientists can name, reason about, and test. Much like ConcepPath in digital pathology that we covered earlier in this series, this paper hints at a future where AI supports concept-level ‘reasoning,’ not just classification.

For Early-Career Scientists

Interpretability isn’t just about trust, it’s also critical for scientific translation. These models may surface patterns that align with biology, but the real opportunity is in bridging those signals to concepts we recognize, can reason about, and critically, can test experimentally. That’s how interpretability becomes a tool for discovery, not because the model “knows” biology, but because we can now ask better questions about what it might be pointing to.
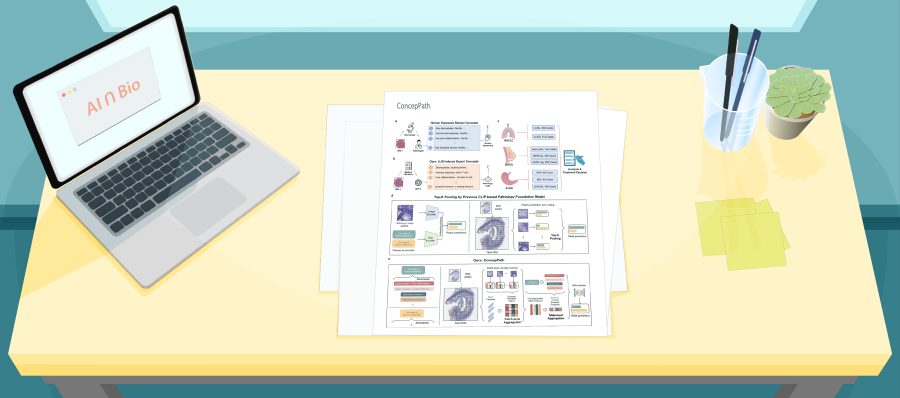
Illustration of a desk with figures from a paper on ConcepPath

From Better Models to Better Questions: A Pathology AI Rethink

This week’s AI ∩ Bio: Reading the Revolution series covers ConcepPath, a new framework that blends expert-derived pathology concepts with deep learning to improve both accuracy and interpretability in histopathology image analysis. Instead of relying only on slide-level labels (e.g., “adenocarcinoma”), ConcepPath uses GPT-4 to extract detailed visual concepts from medical literature and aligns them with tissue regions using vision-language models trained on pathology image–text pairs, helping explain predictions in terms that reflect how diagnoses are taught, documented, and defended in clinical practice.

Scientific Approach

Most AI models for whole slide images (WSIs) use Multiple Instance Learning (MIL); they divide slides into patches, analyze each one, and then aggregate the predictions. This works for classification but offers little insight into why a decision was made. NOTE: more on the ‘standard’ approach in the carousel. ConcepPath adds a critical layer: concept alignment. First, GPT-4 infers visual pathology features from peer-reviewed literature—these become expert-informed concepts. The model then learns additional data-driven patterns directly from the images themselves, potentially novel features that improve prediction even if they lack clinical names. These concepts, both known and learned, are aligned with image features using CLIP-style models (Contrastive Language–Image Pretraining, or models that learn to match images and text that describe the same thing). The model then produces similarity maps showing which parts of the tissue match each concept, for example, highlighting keratin pearls in a region suggestive of squamous carcinoma.

These maps improve interpretability, but they do not replicate diagnostic reasoning. Still, this structured mapping makes model outputs more traceable and aligned with how pathologists evaluate slides.

A Step Forward in Trustworthy AI?

ConcepPath signals a strategic evolution in diagnostic AI—from black-box performance to structured, clinically-aligned transparency. While attention maps and saliency overlays are increasingly common, ConcepPath distinguishes itself by embedding domain knowledge into the model architecture itself. It doesn’t just show where the model looked—it tells us what features it saw.

For early-career researchers, this paper is a reminder that innovation doesn’t always come from better algorithms—it often comes from asking deeper questions. In this case, the authors asked: What would it take for AI to reason with the same visual vocabulary and decision cues as a pathologist? That mindset led to a model that’s both potentially better and more explainable. In computational medicine, it’s this pairing of technical skill and conceptual clarity that sets the stage for meaningful impact.

Powered by WordPress & Theme by Anders Norén