This week’s AI ∩ Bio: Reading the Revolution post explores a new paper tackling one of the biggest challenges in AI for biology: interpretability.
Specifically, how can we tell what genomic transformer models are learning and whether those internal patterns map to real biological concepts?
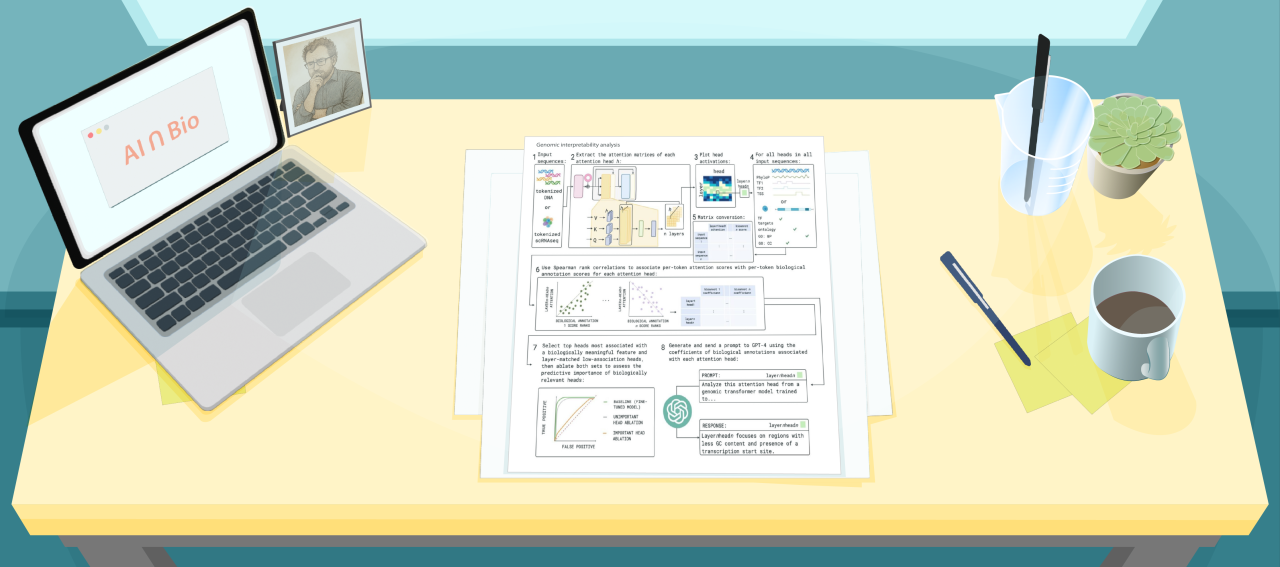
The study proposes a systematic framework to analyze attention heads in models like DNABERT and scGPT. It reveals that many attention heads naturally align with key biological features—such as transcription start sites, sequence motifs (e.g., TATAAA), GC content, conservation scores, and Gene Ontology categories like “neuron projection” or “mitochondrial membrane.” This interpretability emerges even during self-supervised pre-training and strengthens with task-specific fine-tuning.
Key Findings
- Attention heads develop strong correlations with biologically meaningful features.
- These heads tend to be more important for predictive performance, as shown by ablation experiments.
- Interpretability is shaped by tokenization strategy (e.g., overlapping vs. non-overlapping k-mers).
- GPT-4 was used to generate descriptive summaries of head activity (e.g., “TATA box detector”)—but these require validation, as they can miss label-specific nuance.
Limitations
- Correlation ≠ causation: attention may highlight a feature without depending on it for prediction.
- Current analyses treat attention heads in isolation—without clustering or organizing them into higher-level “concept modules.”
- GPT-4 summaries, while useful, may overgeneralize or obscure context-dependent patterns.
Why This Matters
This work moves the field closer to a compelling vision: transformer models that don’t just output predictions, but expose interpretable biological patterns that scientists can name, reason about, and test. Much like ConcepPath in digital pathology that we covered earlier in this series, this paper hints at a future where AI supports concept-level ‘reasoning,’ not just classification.

More in this series
- ChatNT: The future of biological assistants—or a mirage in a lab coat?
- GET: A Foundation Model for Transcription, Still Between Promise and Proof
- X-Atlas/Orion: Your Model is Only as Good as Your Training Data
- From Better Models to Better Questions: A Pathology AI Rethink
- The Model Isn’t the Magic: How Cytoland shows that domain expertise—not just deep learning—is what makes AI in biology work.
- Boltz-2: How much can 3D structure really tell us about molecular binding energetics?
- Investigating the volume and diversity of data needed for generalizable antibody–antigen ΔΔG prediction
- Beyond Binding: Rethinking Drug Design in the Age of AI and Structural Biology
- Testing the Physics Beneath the Predictions Beyond RMSD: What AlphaFold3 Really Understands
- Hype, Hurdles, and Hepatotoxicity: A Bold Step for AI-Designed Drugs, But Still Miles to Go
- When Complexity Misleads
- What Are Genomic Transformers Actually Learning?
- mRNABench and the Future of AI in Biology: Why Domain Knowledge Wins
- OncoGAN Creates Synthetic Cancer Genomes, Opening New Paths for Privacy-Preserving Precision Oncology
- Readable Rules, Testable Models: A New Grammar for Virtual Cells
- Multimodal CustOmics: Fusing Pathology Images and Tumor Genomics for Next-Gen Cancer Diagnostics
- Beyond Perturbation Simulations: PDGrapher Shows a Faster Way to Identify Actionable Targets
- Can AI design epigenetic anti-aging strategies?
- What happens when physicians use GPT-4 for diagnosis
- Can generative AI predict emergent phenomena?
- DeepSomatic and the question of how AI learns from itself
- Toward Mechanism-Centric Interpretability in Genomic Machine Learning
- From AlphaEvolve to DeepEvolve: What We’re Learning About Machine-Led Scientific Discovery
- Kosmos and the Culture of Discovery
- From Embeddings to Insight
- From Prediction to Explanation: How BIOREASON Reframes Genomic AI as a Reasoning Problem
- AI Models Need Better Truth—Platinum Pedigree Shows How
- From Evolutionary Intolerance to Clinical Insight: What popEVE Teaches Us About Missense Variants
- Interpretable Latent Spaces, Messy Biology: What AUTOENCODIX Teaches Us About Autoencoders in the Wild
- The Gene Ontology Knowledgebase in 2026
For Early-Career Scientists
Interpretability isn’t just about trust, it’s also critical for scientific translation. These models may surface patterns that align with biology, but the real opportunity is in bridging those signals to concepts we recognize, can reason about, and critically, can test experimentally. That’s how interpretability becomes a tool for discovery, not because the model “knows” biology, but because we can now ask better questions about what it might be pointing to.
Comments
Powered by WP LinkPress