
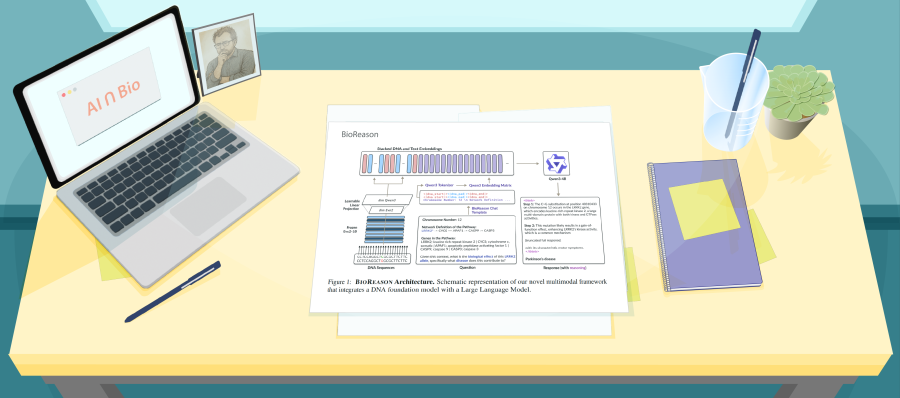
While DNA foundation models like Evo2 and Nucleotide Transformer can encode genomic sequences into dense, information-rich embeddings, they still operate as black boxes—excellent at prediction, poor at explaining why. Large language models offer the opposite tradeoff: they excel at generating explanations but treat DNA as unstructured text, without any built-in understanding of motifs, regulatory grammar, or sequence constraints.
What BIOREASON Does
BIOREASON introduces a multimodal architecture that fuses:
- A frozen DNA foundation model to encode biological sequence semantics
- A fine-tuned LLM that ingests both the embeddings and natural-language context
This pairing enables:
- Natural-language reasoning grounded (at least in theory) in genomic content
- Generation of interpretable, mechanistic chains (variant → pathway → phenotype)
- Improved predictive performance relative to either the DNA FM or LLM alone
But what do DNA embeddings “mean”?
Short answer: we don’t know—and that uncertainty is inherent to foundation models.
- These embeddings are latent representations learned through massive unsupervised training.
- They’re presumed to encode motifs, conservation, splicing signals, or regulatory cues because the model needed those features to solve its training task.
- They are not human-interpretable.
BIOREASON treats these embeddings as a kind of “biological fingerprint,” trusting that an LLM can learn to reason over them with enough supervised examples. The gamble is that:
- The DNA model has learned useful biological grammar
- The LLM can exploit those learned signals to answer new questions
But there’s no explicit decoding or truth-checking of what the embeddings represent internally.
Why reasoning faithfulness still isn’t guaranteed
The <think> traces produced by BIOREASON are not probabilistic, validated, or causally guaranteed. The model “believes” its chain, but you must judge its soundness.
Anthropic’s “Reasoning Models Don’t Always Say What They Think” (Chen et al., 2025) shows why this matters: reasoning-tuned models often rely on subtle internal shortcuts, then fail to verbalize them, generating fluent but misleading explanations. BIOREASON inherits the same risk.
Key concerns:
- Explainability ≠ faithfulness
A coherent chain does not mean the model followed that chain internally. - Potential post-hoc rationalization
The model may rely on correlations or dataset artifacts, then wrap them in a plausible narrative. - Compromised auditability
If the chain isn’t faithful, transparency becomes performative rather than informative. - Hidden biases or shortcut features
The model might use annotation frequency, ClinVar priors, or pathway prevalence without ever stating so. - Lack of mechanistic grounding
True mechanistic understanding would require identifying which embedding dimensions or sequence contexts drove the decision. The <think> chain alone cannot provide this.
Let’s step back: What’s genuinely novel here?
Despite its limitations, BIOREASON introduces several meaningful advances for the field.
Fusion of Biological Foundation Models with Language Reasoning
Traditional models split into two camps:
- Models that understand sequence biology (Enformer, Evo2, Nucleotide Transformer)
- Models that generate explanations (GPT-style LLMs)
BIOREASON bridges these worlds:
- Anchors reasoning in sequence-aware embeddings
- Trains the LLM to produce structured, biologically grounded explanations
Why this matters
It reframes variant interpretation as causal narrative inference—a closer match to how human scientists reason.
Structured Explainability via <think> Tokens
Most genomics tools output scores or saliency maps. BIOREASON outputs reasoning.
- <think> traces formalize a stepwise, human-auditable chain
- Explanation becomes part of the training objective, not a reverse-engineered artifact
Why this matters
This is one of the first genomics models to explicitly train for mechanistic-style explanation.
A Real Multimodal Interface for Genomics
Multimodal architectures (image+text, audio+text) are flourishing, but genomics has lagged.
BIOREASON shows:
- DNA sequences can be treated as semantic inputs
- LLMs can generate biologically coherent outputs when grounded in embeddings
Why this matters
It opens the door to models that integrate DNA, RNA, protein, expression, and literature signals—moving us nearer to true AI lab partners.
Raises Critical Questions About Faithfulness
By making reasoning visible, BIOREASON forces the field to confront fundamental issues:
- What does it mean for a model to “understand” a variant?
- How do we measure explanation fidelity, not just fluency?
- How can we prove the model’s logic is driven by sequence rather than language priors?
Why this matters
These questions will shape the evaluation standards for biological AI over the next decade.

Final Thought
BIOREASON’s contribution isn’t that it solves variant interpretation. It’s that it reframes the problem as reasoning, not classification. It pushes us closer to models that narrate mechanistic hypotheses—but it also reminds us why faithfulness, causal testing, and biological grounding matter just as much as model performance.
With stronger embeddings, uncertainty calibration, perturbation tests, and wet-lab validation, this line of work could become a cornerstone of how AI collaborates with scientists in the years ahead.
