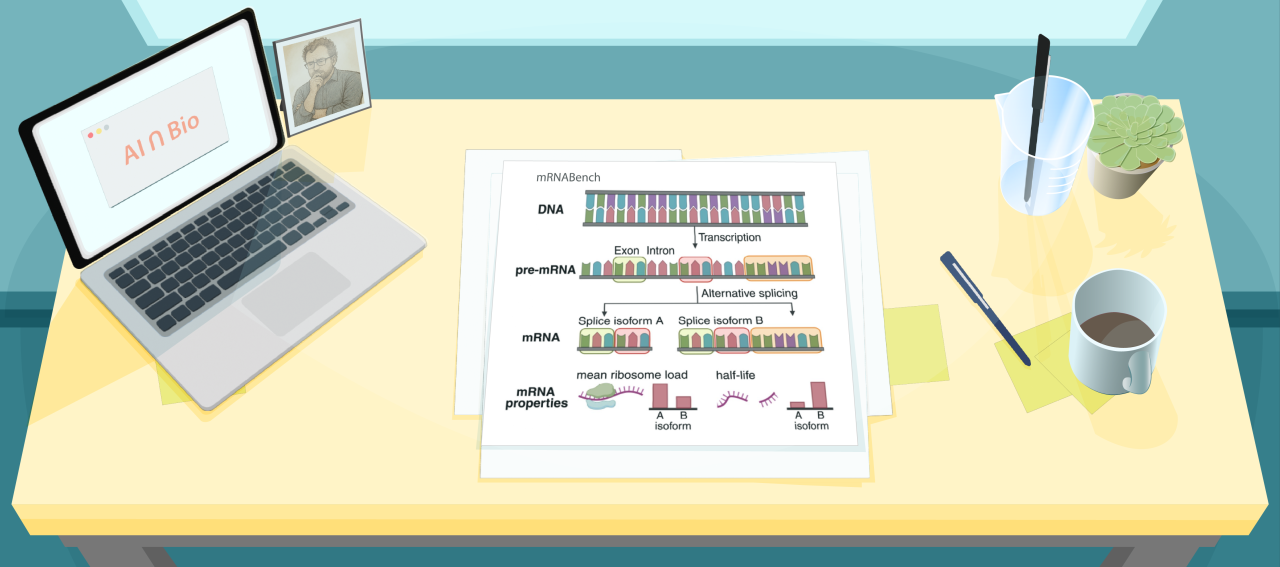
This week’s paper, “MRNABENCH: A curated benchmark for mature mRNA property and function prediction,” introduces a benchmarking framework for evaluating whether foundation models are truly learning features of RNA biology, specifically as it relates to mRNA. Messenger RNA is one of the most information-dense molecules in biology, carrying not only the coding sequence but also a layered regulatory grammar across UTRs, splice isoforms, and motifs (we won’t get into modifications today, but there’s that too). These features govern stability, localization, and translation efficiency, dimensions central to both basic biology and therapeutic design.
Scientific Insight
What makes this work stand out is its clear demonstration that models designed with biological principles in mind rival or exceed massive models in many tasks, highlighting biologically grounded design as equally important as scale. The authors show that models aligned with transcript biology can match or even surpass billion-parameter models on key benchmarks, delivering strong results at far less computational cost. Equally important, their rigorous approach to data splitting (random, k-mer, and homology-based) reveals a common blind spot in genomic machine learning, where models often appear to generalize but are simply re-identifying homologous sequences. In other words, success was linked to respecting the rules of molecular biochemistry, not just piling on more unlabeled data.
Leadership Angle
For leaders in diagnostics and therapeutics, this work is a powerful reminder: scaling isn’t everything. In an era where compute budgets are skyrocketing, the true differentiator may be how well we integrate domain knowledge into AI design. Frameworks like mRNABench help us separate hype from genuine progress, ensuring that models capture biologically meaningful signals, an essential step toward reliable applications in biology and therapeutics.

More in this series
- ChatNT: The future of biological assistants—or a mirage in a lab coat?
- GET: A Foundation Model for Transcription, Still Between Promise and Proof
- X-Atlas/Orion: Your Model is Only as Good as Your Training Data
- From Better Models to Better Questions: A Pathology AI Rethink
- The Model Isn’t the Magic: How Cytoland shows that domain expertise—not just deep learning—is what makes AI in biology work.
- Boltz-2: How much can 3D structure really tell us about molecular binding energetics?
- Investigating the volume and diversity of data needed for generalizable antibody–antigen ΔΔG prediction
- Beyond Binding: Rethinking Drug Design in the Age of AI and Structural Biology
- Testing the Physics Beneath the Predictions Beyond RMSD: What AlphaFold3 Really Understands
- Hype, Hurdles, and Hepatotoxicity: A Bold Step for AI-Designed Drugs, But Still Miles to Go
- When Complexity Misleads
- What Are Genomic Transformers Actually Learning?
- mRNABench and the Future of AI in Biology: Why Domain Knowledge Wins
- OncoGAN Creates Synthetic Cancer Genomes, Opening New Paths for Privacy-Preserving Precision Oncology
- Readable Rules, Testable Models: A New Grammar for Virtual Cells
- Multimodal CustOmics: Fusing Pathology Images and Tumor Genomics for Next-Gen Cancer Diagnostics
- Beyond Perturbation Simulations: PDGrapher Shows a Faster Way to Identify Actionable Targets
- Can AI design epigenetic anti-aging strategies?
- What happens when physicians use GPT-4 for diagnosis
- Can generative AI predict emergent phenomena?
- DeepSomatic and the question of how AI learns from itself
- Toward Mechanism-Centric Interpretability in Genomic Machine Learning
- From AlphaEvolve to DeepEvolve: What We’re Learning About Machine-Led Scientific Discovery
- Kosmos and the Culture of Discovery
- From Embeddings to Insight
- From Prediction to Explanation: How BIOREASON Reframes Genomic AI as a Reasoning Problem
- AI Models Need Better Truth—Platinum Pedigree Shows How
- From Evolutionary Intolerance to Clinical Insight: What popEVE Teaches Us About Missense Variants
- Interpretable Latent Spaces, Messy Biology: What AUTOENCODIX Teaches Us About Autoencoders in the Wild
- The Gene Ontology Knowledgebase in 2026
Mentorship Angle
For early-career scientists, the takeaway is clear: don’t lose sight of the biology. It’s tempting to chase ever-larger models or datasets, but this paper shows the biggest leaps often come from framing the right questions and aligning methods with molecular reality. Building rigorous standards, designing smarter architectures, and spotting blind spots in evaluation are contributions that will shape the field for years to come. If you’re wondering how to make your mark, focus on creating the kind of cross-domain exchange where the biological questions and scientific rigor are foundational to your approach, not an afterthought.
Comments
Powered by WP LinkPress