Leadership in Biotech

Tag: machine learning

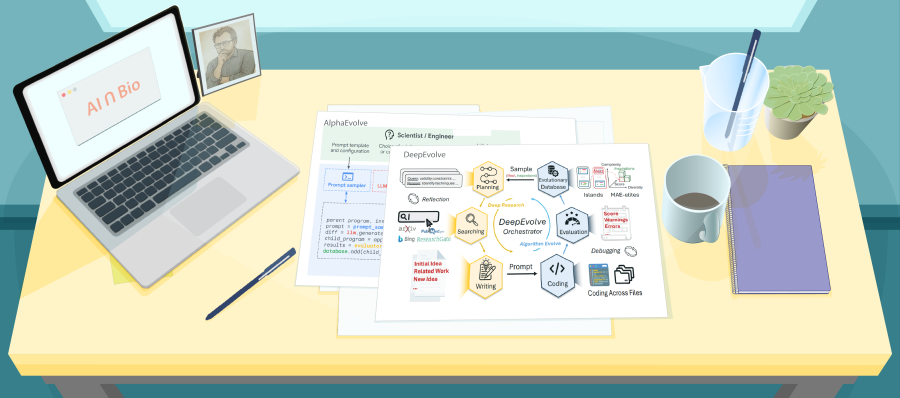
Illustration of a desk with figures from recent papers about DeepEvolve and AlphaEvolve

From AlphaEvolve to DeepEvolve: What We’re Learning About Machine-Led Scientific Discovery

Over the past year, AlphaEvolve (DeepMind) and DeepEvolve (Liu et al.) have taken on one of science’s most audacious challenges: can machines not only execute discovery but originate it? Both leverage large language models (LLMs) to iteratively evolve algorithms through feedback and automated evaluation.

AlphaEvolve reframed discovery as code evolution: LLMs proposing edits, testing them, and optimizing against performance scores. DeepEvolve extends this paradigm by integrating deep research: literature retrieval, structured reasoning, multi-file implementation, and automatic debugging. Together, they signal a shift from code-writing tools to more active scientific collaborators and raise foundational questions about what counts as “understanding.”

Scientific Insight

AlphaEvolve’s achievements are real and impressive: it discovered a novel algorithm for 4×4 matrix multiplication, improving on a benchmark that had stood since 1969. But its limitations are equally instructive. When optimization is tethered entirely to scalar reward signals, models risk learning how to perform rather than how to understand.

DeepEvolve addresses some of this by incorporating retrieval-augmented reasoning and grounded iteration, showing measurable gains across nine domains—from molecular property prediction to polymer engineering. Yet the deeper challenge persists: these systems can refine heuristics, but they cannot yet articulate principles; the boundary between discovery and reward chasing remains unresolved.

Leadership Angle

For R&D leaders in life sciences or diagnostics, these systems are both technical achievements and strategic case studies.

Peter Drucker once warned: “What gets measured gets managed—even when it’s pointless to measure or manage it.” In the context of these papers, the risk is clear: if we measure only performance, we may optimize into blind alleys. The opportunity lies in designing systems (and organizations!) that ask better questions, not just produce better scores.

Mentorship Angle

For early-career scientists, the message isn’t to fear or avoid these tools (please don’t, these tools are amazing!), but to understand their limitations. AlphaEvolve and DeepEvolve can automate exploration, but perhaps not judgment. They can generate thousands of hypotheses in hours, but still depend on human insight to distinguish signal from noise. And require careful thought in setting up reward systems that uncover real meaning in the context you care about.

In a world where even machines can “research,” the defining trait of good science will be the discipline to ask whether improvement is meaningful, not just measurable. That’s the work of real discovery and no algorithm can evolve that for us (at least not yet!).
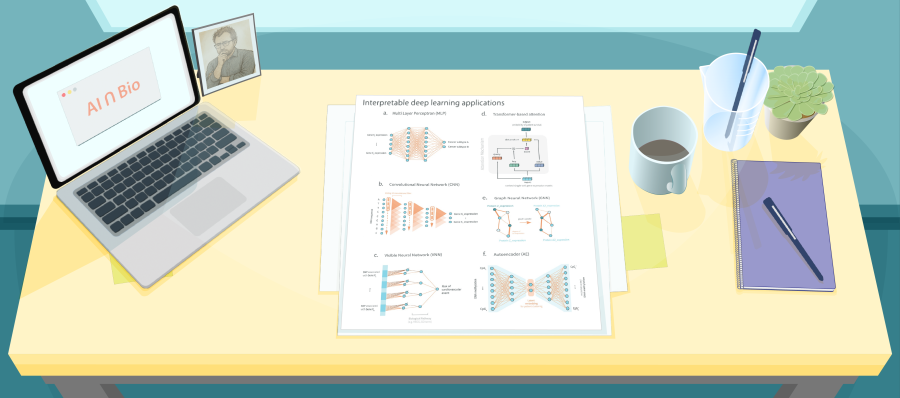
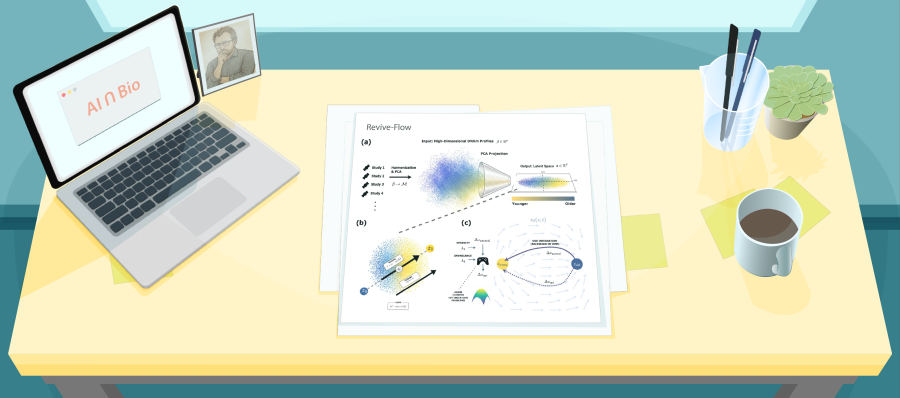
Illustration of a desk with a figure from a recent paper about interpretable deep learning applications

Toward Mechanism-Centric Interpretability in Genomic Machine Learning

Rather than reviewing a paper, this week’s post takes a broader view on where we are at with respect to interpretability in genomics ML models.

As the field continues to rigorously interrogate the most recent ML genomics models, it has become clear that it’s incredibly easy to fool ourselves about what these models are learning, what they can predict, and how to do better.

One component of improving on the current state is to get more serious about interpretability. Most interpretability efforts remain retrospective—feature rankings, attention maps, or gradient plots that rationalize outputs but rarely reveal how, or whether, the model’s reasoning aligns with biology.

If we care about mechanism (and we should, because this is how models become more extensible and useful), we need a shift in stance. Interpretability should not be a gloss applied at the end of analysis, it should be part of how models are built, tested, and revised.

Here I posit that there are four questions worth asking of every architecture and dataset to help us move in that direction.

What are we interpreting: mechanisms, predictions, or confounds?

Each target demands a different standard of evidence. Mechanistic interpretability seeks causal structure; predictive interpretability seeks justification; artifact detection seeks bias. Without distinguishing them, we risk mistaking coherence for truth.

What biological hypotheses are encoded in the model architecture?

Every design choice carries an implicit worldview: MLPs flatten dependencies; GNNs canonize known graphs; transformers elevate context as signal. These are not neutral—they shape what the model is capable of discovering, and what it will systematically miss.

Can multimodal data be used to falsify interpretations?

Adding data layers isn’t just about increasing modeling power. Done correctly, an additional modality can act to challenge the others, serving as an independent test of whether the model’s inferences hold up under a different lens.

How can interpretability inform model iteration?

Used well, interpretability is diagnostic. It surfaces blind spots: missing biological priors, unrepresentable hierarchies, or architectural constraints that obscure mechanism. Those failures are invitations to refine both model and experiment.

Why it matters

Interpretability is not a transparency feature; it’s a scientific claim about correspondence between computation and biology.
And like any scientific claim, it must be testable, falsifiable, and revised in light of evidence.

Illustration of a desk with a figure from a recent paper about Revive-Flow

Can AI design epigenetic anti-aging strategies?

This week’s AI ∩ Bio paper, Revive-Flow, asks a provocative question: what if we could simulate aging entirely on a computer and then understand how to “rewind” it?

The authors use blood DNA methylation data (chemical tags on DNA that shift with age) and train a machine learning model to treat aging as a trajectory.

Their claim is that with the right edits to just a handful of these DNA sites, you could in theory nudge a biological entity toward a younger state. It’s an imaginative reframing of how AI might tackle one of biology’s biggest questions.

Scientific Insight

The innovation here is modeling aging as a dynamic system rather than a static measurement. Most previous approaches, known as “epigenetic clocks,” simply predict a person’s age from DNA patterns. Revive-Flow goes further by simulating what would happen if you tried to shift those patterns in reverse. The authors design a mathematically elegant way of proposing “edits” and test whether these moves make the sample look younger to their own model.

Where it falls short is in the biology: the proposed edits are not checked against known aging pathways, not validated in cells, and not benchmarked against established clocks that are tied to health outcomes. And the statistical choices, like reducing hundreds of thousands of DNA sites down to a few thousand components, risk mixing true age signals with noise from lab effects or blood cell composition.

What we’re left with is an interesting hypothesis generator for methylation edits, but not evidence that we can computationally design, let alone achieve, cellular rejuvenation.

Leadership Angle

For those of us in diagnostics, there’s a lesson here. Computational innovation can outpace biological grounding, and when it does, it’s tempting to overstate claims. In a field as consequential as aging, epistemic humility matters. A model like Revive-Flow could eventually become a powerful hypothesis generator for methylation interventions, but only if paired with rigorous external benchmarking and wet-lab validation. For organizations, the takeaway is to create systems where bold ideas are encouraged, but where claims are calibrated to the level of evidence, because credibility is an asset you can’t afford to squander.

Mentorship Angle

For early-career scientists, this paper offers a reminder: the most elegant models are still only as strong as their grounding in biology. Don’t shy away from ambitious computational approaches, but be clear about what’s hypothesis and what’s mechanism. Your career will be built not just on the ideas you chase, but on the discipline with which you test them. Sometimes the most valuable contribution is not the model itself, but the clarity it brings to the next set of experiments.

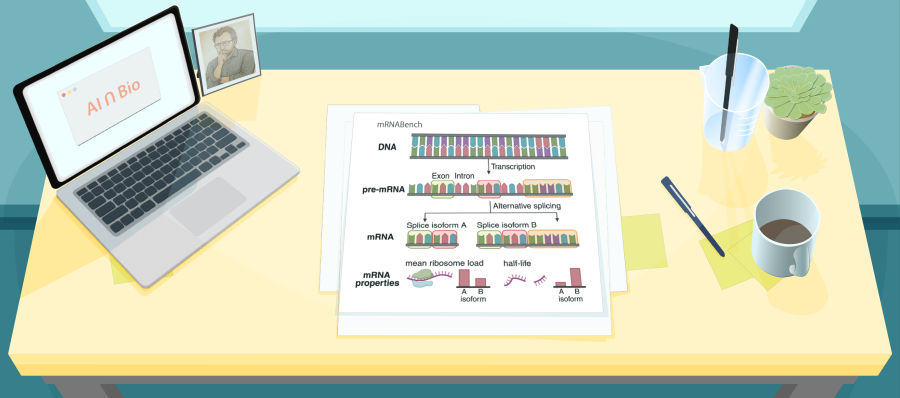
Illustration of a desk with a figure from a recent paper about mRNABench

mRNABench and the Future of AI in Biology: Why Domain Knowledge Wins

This week’s paper, “MRNABENCH: A curated benchmark for mature mRNA property and function prediction,” introduces a benchmarking framework for evaluating whether foundation models are truly learning features of RNA biology, specifically as it relates to mRNA. Messenger RNA is one of the most information-dense molecules in biology, carrying not only the coding sequence but also a layered regulatory grammar across UTRs, splice isoforms, and motifs (we won’t get into modifications today, but there’s that too). These features govern stability, localization, and translation efficiency, dimensions central to both basic biology and therapeutic design.

Scientific Insight

What makes this work stand out is its clear demonstration that models designed with biological principles in mind rival or exceed massive models in many tasks, highlighting biologically grounded design as equally important as scale. The authors show that models aligned with transcript biology can match or even surpass billion-parameter models on key benchmarks, delivering strong results at far less computational cost. Equally important, their rigorous approach to data splitting (random, k-mer, and homology-based) reveals a common blind spot in genomic machine learning, where models often appear to generalize but are simply re-identifying homologous sequences. In other words, success was linked to respecting the rules of molecular biochemistry, not just piling on more unlabeled data.

Leadership Angle

For leaders in diagnostics and therapeutics, this work is a powerful reminder: scaling isn’t everything. In an era where compute budgets are skyrocketing, the true differentiator may be how well we integrate domain knowledge into AI design. Frameworks like mRNABench help us separate hype from genuine progress, ensuring that models capture biologically meaningful signals, an essential step toward reliable applications in biology and therapeutics.

Mentorship Angle

For early-career scientists, the takeaway is clear: don’t lose sight of the biology. It’s tempting to chase ever-larger models or datasets, but this paper shows the biggest leaps often come from framing the right questions and aligning methods with molecular reality. Building rigorous standards, designing smarter architectures, and spotting blind spots in evaluation are contributions that will shape the field for years to come. If you’re wondering how to make your mark, focus on creating the kind of cross-domain exchange where the biological questions and scientific rigor are foundational to your approach, not an afterthought.

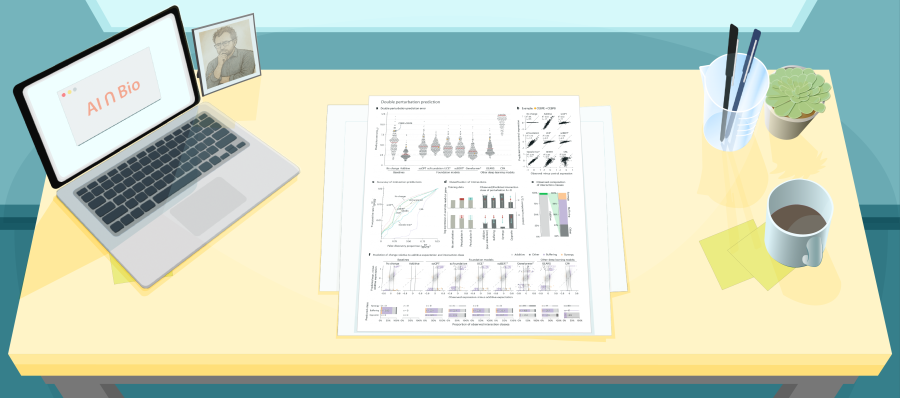
Illustration of a desk with a figure from a recent paper about Deep-learning-based gene perturbation

When Complexity Misleads

In this week’s AI ∩ Bio paper, we look at a multi-dataset benchmark where deep learning models trained to predict single-cell perturbation outcomes did not outperform two deliberately simple baselines: “assume nothing changes” and “predict the additive combination of single perturbations.” Performance improved when models were reduced to just their internal embeddings and a linear decoder—no deep layers, just a direct projection from embedding space to gene expression. In other words, the models had learned biologically meaningful representations during training, but using those representations to make predictions through a complex decoder often made things worse.

This result may not surprise those familiar with traditional machine learning approaches. As the bias–variance tradeoff reminds us: when signal is weak and noise is high, simpler models often generalize better and overfit less, leading them to outperform more complex alternatives.

This study revealed both conditions:

  • The signal from genetic perturbations is often modest or additive.
  • The noise in single-cell gene expression is high, due to dropout, amplification bias, and biological variability.

If your model must detect subtle shifts in expression, but your measurement system is saturated with noise, then even an optimal model will struggle to generate meaningful predictions. And a large model may do worse, because it fits spurious correlations that simpler models ignore.

Before adding more architecture, it’s worth asking:

  • Have we clearly defined our outcome?
  • Do we understand the system we are working with?
  • Can our data realistically support the question we’re asking?

Otherwise, we risk building a computational Rube Goldberg machine: impressive, fragile, and ultimately unclear.

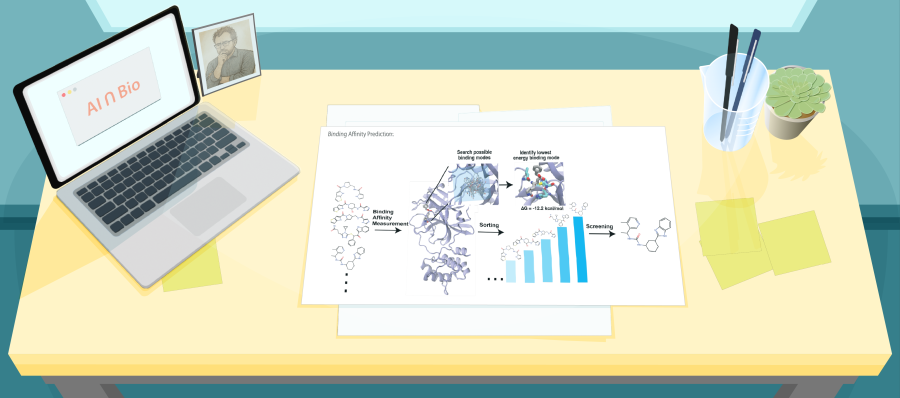
Illustration of a desk with a figure from a recent paper about binding affinity predictions

Beyond Binding: Rethinking Drug Design in the Age of AI and Structural Biology

In molecular design, we often prioritize what’s measurable over what’s meaningful.

For decades, binding affinity has served as a cornerstone of early-stage drug discovery, not because it captures biological function in full, but because it’s one of the few properties we can quantify systematically and optimize across large libraries.

Now, as AI models generate binders faster than we can validate them, we must ask: What exactly are we optimizing for? And what datasets are we training on?

What we know:

  • Strong binding doesn’t guarantee efficacy
  • Residence time and conformational flexibility can matter more than affinity
  • Cellular context — target expression, pathway crosstalk, and off-target interactions — often dictates outcome in clinical applications

Yet much of the public data — and many AI training sets — still orbit around Kd, IC₅₀, and docking scores. These are abundant and easy to label, but they capture only a narrow slice of pharmacological reality (and we’re not even accounting for the fact that these measurements are highly dependent on the specific conditions- buffer, temperature, etc).

If we train models on what’s easy to measure, we shouldn’t be surprised when they generate molecules that impress in silico — and disappoint in vivo.

The problem isn’t that binding doesn’t matter. It does. The problem is that binding isn’t biology.

Toward More Meaningful Models

To do better, we’ll need to:

  • Incorporate multi-parametric data: kinetics, permeability, metabolism, toxicity, immune activation
  • Train models to include mechanism and uncertainty, not just affinity
  • Elevate datasets that link structure to systems, not just structure to scores

The best work ahead won’t just generate molecules; it will surface better models about how they work, and where they fail in the journey from discovery to clinic.

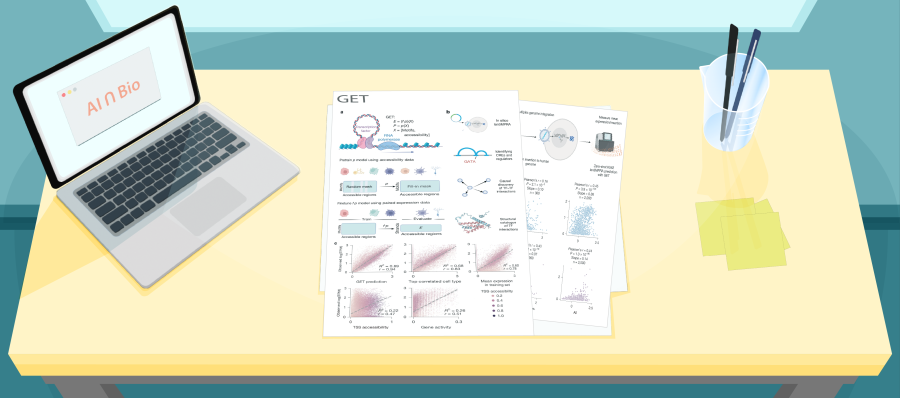
Illustration of a desk with figures from a paper on GET

GET: A Foundation Model for Transcription, Still Between Promise and Proof

Tl;dr Statistical generalization isn’t scientific understanding—don’t confuse prediction with insight. Foundation models like GET may predict gene expression patterns from clean data and learn patterns that appear biologically meaningful, but that’s not the same as understanding transcriptional regulation. Its outputs should be treated as hypotheses to interrogate—not definitive answers.

This week’s AI ∩ Bio: Reading the Revolution series features a recent Nature paper on “General Expression Transformer” (GET), a deep learning model trained to predict gene expression across 213 human cell types using DNA sequence and chromatin accessibility data. It’s ambitious: a transformer architecture that claims to learn the “grammar” of transcription, generalize across diverse cell types, and model long-range interactions between enhancers and promoters, as well as between transcription factors (TFs). In one case study, the authors link a leukemia-associated genetic variant (a SNP) to a disrupted protein–protein interaction between TFs, using AlphaFold structural modeling.

The aim is compelling—bringing together machine learning, epigenomics, and protein structure prediction. GET outperforms previous models like Enformer on several tasks, including prediction of reporter assay results (like MPRA) and identifying enhancer–promoter relationships. It also offers interpretability features, such as motif-level and region-level importance scores, which are an improvement over traditional “black box” models. And yes, it suggests potential utility: in theory, GET could aid in prioritizing noncoding variants or mapping regulatory networks.

But here’s the catch: GET requires both DNA sequence and chromatin accessibility data from the specific cell type of interest. You can’t simply input a variant file (like a VCF from whole-genome sequencing) and get back useful predictions. At best, you can explore hypotheses using accessibility data from public reference tissues—helpful for interpreting genome-wide association study (GWAS) results, but not yet practical for clinical use.

The generalization here is statistical—not biological, and certainly not clinical. GET was trained on harmonized, high-quality single-cell datasets from healthy human tissues. It performs well on similar data it hasn’t seen before—but that’s a narrow slice of human biology. Clinical samples, especially those from inflamed, cancerous, or drug-altered environments, often have chromatin landscapes and transcriptional programs that fall outside the model’s training distribution. High correlation on held-out healthy data doesn’t guarantee reliability under pathological conditions. The model is rigorous in its computation—but its clinical readiness remains speculative.

To early-career scientists: Always know the limits of your tools. Foundation models can learn statistical patterns that look biological, without understanding the underlying mechanisms. A model trained on chromatin accessibility may capture useful correlations, but not the dynamic, causal logic of transcription. And interpretability tools like motif importance scores are only meaningful if they lead to testable, falsifiable predictions that hold up under rigorous testing. Treat every output as a hypothesis to challenge.

Powered by WordPress & Theme by Anders Norén