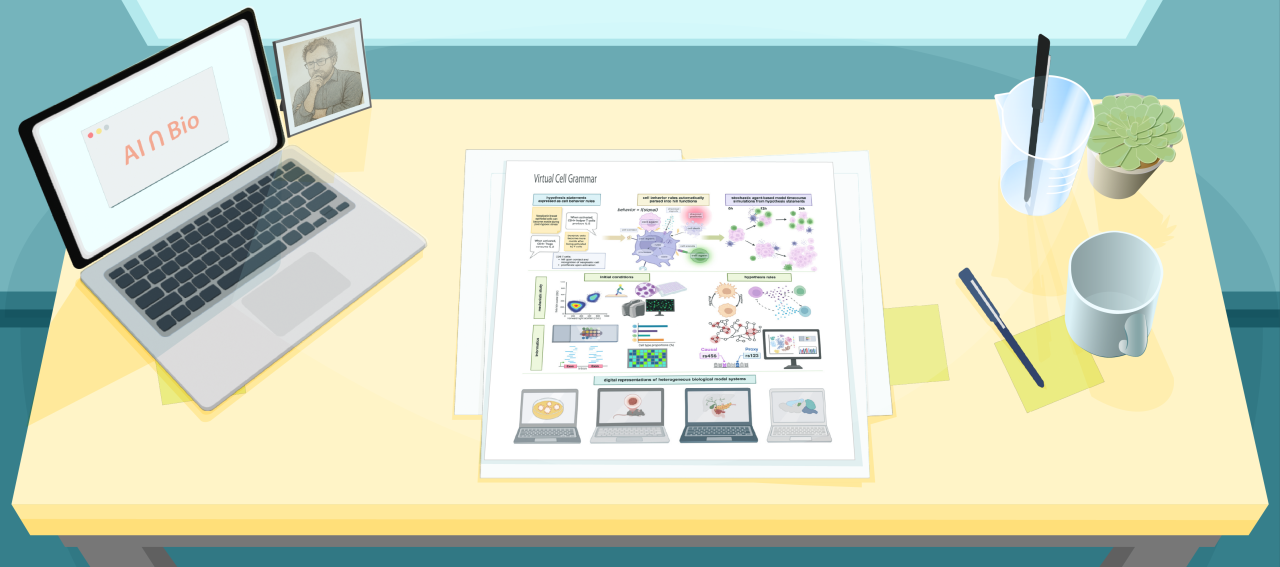
Virtual Cell Models are all the rage right now, and this week’s AI ∩ Bio paper covers one recent paper that aims to democratize this approach by encoding complex multicellular dynamics in plain language.
This paper introduces a plain-language “cell behavior hypothesis grammar” that turns rules like “oxygen decreases necrosis” into executable agent-based models. The aim is to let researchers build virtual experiments directly from human-readable statements, initialize them with single-cell or spatial data, and test how cell–cell and tissue dynamics unfold.
Why it matters: it makes modeling more accessible, assumptions more transparent, and experiments easier to prioritize.
Scientific Insight
At its core, the grammar provides dictionaries of signals (what cells sense) and behaviors (what cells do), plus simple response forms, so a one-line rule becomes math the simulator can execute. The paper shows this through diverse examples: hypoxic tumor growth, PDAC invasion seeded from Visium data, tumor–immune dynamics, an EGF “go vs. grow” test validated with organoids and cell tracking, and cortical layer formation modeled from asymmetric division rules.
If you’re new to this, the big idea is: start with rules you can read, tie parameters to data where possible, and test which parameters truly drive outcomes.
Leadership Angle
For diagnostics and translational leaders, this work is a pragmatic step toward virtual cell laboratories: models initialized from tissue data can be used to explore therapy combinations and microenvironmental dynamics before committing wet-lab time. The scope is still local-tissue, not clinical, but when used carefully these grammars act as prioritization engines, or tools to sharpen questions and rank hypotheses.

More in this series
- ChatNT: The future of biological assistants—or a mirage in a lab coat?
- GET: A Foundation Model for Transcription, Still Between Promise and Proof
- X-Atlas/Orion: Your Model is Only as Good as Your Training Data
- From Better Models to Better Questions: A Pathology AI Rethink
- The Model Isn’t the Magic: How Cytoland shows that domain expertise—not just deep learning—is what makes AI in biology work.
- Boltz-2: How much can 3D structure really tell us about molecular binding energetics?
- Investigating the volume and diversity of data needed for generalizable antibody–antigen ΔΔG prediction
- Beyond Binding: Rethinking Drug Design in the Age of AI and Structural Biology
- Testing the Physics Beneath the Predictions Beyond RMSD: What AlphaFold3 Really Understands
- Hype, Hurdles, and Hepatotoxicity: A Bold Step for AI-Designed Drugs, But Still Miles to Go
- When Complexity Misleads
- What Are Genomic Transformers Actually Learning?
- mRNABench and the Future of AI in Biology: Why Domain Knowledge Wins
- OncoGAN Creates Synthetic Cancer Genomes, Opening New Paths for Privacy-Preserving Precision Oncology
- Readable Rules, Testable Models: A New Grammar for Virtual Cells
- Multimodal CustOmics: Fusing Pathology Images and Tumor Genomics for Next-Gen Cancer Diagnostics
- Beyond Perturbation Simulations: PDGrapher Shows a Faster Way to Identify Actionable Targets
- Can AI design epigenetic anti-aging strategies?
- What happens when physicians use GPT-4 for diagnosis
- Can generative AI predict emergent phenomena?
- DeepSomatic and the question of how AI learns from itself
- Toward Mechanism-Centric Interpretability in Genomic Machine Learning
- From AlphaEvolve to DeepEvolve: What We’re Learning About Machine-Led Scientific Discovery
- Kosmos and the Culture of Discovery
- From Embeddings to Insight
- From Prediction to Explanation: How BIOREASON Reframes Genomic AI as a Reasoning Problem
- AI Models Need Better Truth—Platinum Pedigree Shows How
- From Evolutionary Intolerance to Clinical Insight: What popEVE Teaches Us About Missense Variants
- Interpretable Latent Spaces, Messy Biology: What AUTOENCODIX Teaches Us About Autoencoders in the Wild
- The Gene Ontology Knowledgebase in 2026
Lessons for Early-Career Scientists
If you’re early in your career, I would consider two lessons here.
- First, write the biological models down explicitly, framing for yourself how outcomes shift when parameters are perturbed.
- Second, design experiments that rigorously interrogate these models: not to confirm them, but to expose where they fail.
Transparent rulebooks, sensitivity analyses, and reproducible code will accelerate your science regardless of your toolkit.
Virtual Cell Grammar formalizes implicit scientific thinking, but its value ultimately depends on how it’s used to design falsifiable experiments.
Comments
Powered by WP LinkPress