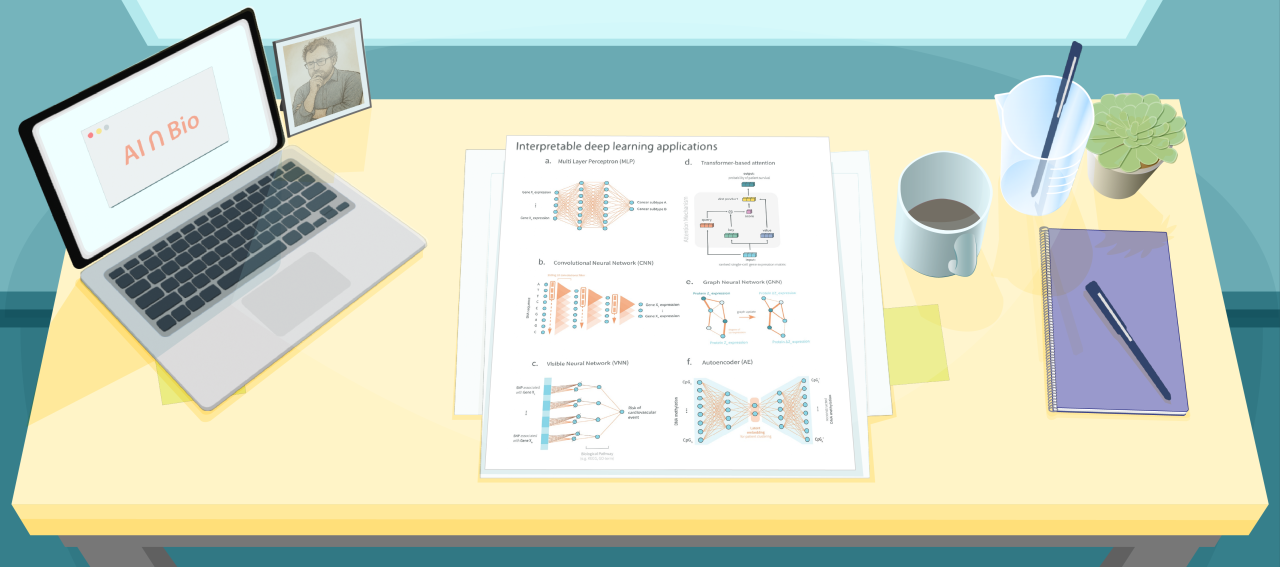
Rather than reviewing a paper, this week’s post takes a broader view on where we are at with respect to interpretability in genomics ML models.
As the field continues to rigorously interrogate the most recent ML genomics models, it has become clear that it’s incredibly easy to fool ourselves about what these models are learning, what they can predict, and how to do better.
One component of improving on the current state is to get more serious about interpretability. Most interpretability efforts remain retrospective—feature rankings, attention maps, or gradient plots that rationalize outputs but rarely reveal how, or whether, the model’s reasoning aligns with biology.
If we care about mechanism (and we should, because this is how models become more extensible and useful), we need a shift in stance. Interpretability should not be a gloss applied at the end of analysis, it should be part of how models are built, tested, and revised.
Here I posit that there are four questions worth asking of every architecture and dataset to help us move in that direction.
What are we interpreting: mechanisms, predictions, or confounds?
Each target demands a different standard of evidence. Mechanistic interpretability seeks causal structure; predictive interpretability seeks justification; artifact detection seeks bias. Without distinguishing them, we risk mistaking coherence for truth.
What biological hypotheses are encoded in the model architecture?
Every design choice carries an implicit worldview: MLPs flatten dependencies; GNNs canonize known graphs; transformers elevate context as signal. These are not neutral—they shape what the model is capable of discovering, and what it will systematically miss.
Can multimodal data be used to falsify interpretations?
Adding data layers isn’t just about increasing modeling power. Done correctly, an additional modality can act to challenge the others, serving as an independent test of whether the model’s inferences hold up under a different lens.
How can interpretability inform model iteration?
Used well, interpretability is diagnostic. It surfaces blind spots: missing biological priors, unrepresentable hierarchies, or architectural constraints that obscure mechanism. Those failures are invitations to refine both model and experiment.

More in this series
- ChatNT: The future of biological assistants—or a mirage in a lab coat?
- GET: A Foundation Model for Transcription, Still Between Promise and Proof
- X-Atlas/Orion: Your Model is Only as Good as Your Training Data
- From Better Models to Better Questions: A Pathology AI Rethink
- The Model Isn’t the Magic: How Cytoland shows that domain expertise—not just deep learning—is what makes AI in biology work.
- Boltz-2: How much can 3D structure really tell us about molecular binding energetics?
- Investigating the volume and diversity of data needed for generalizable antibody–antigen ΔΔG prediction
- Beyond Binding: Rethinking Drug Design in the Age of AI and Structural Biology
- Testing the Physics Beneath the Predictions Beyond RMSD: What AlphaFold3 Really Understands
- Hype, Hurdles, and Hepatotoxicity: A Bold Step for AI-Designed Drugs, But Still Miles to Go
- When Complexity Misleads
- What Are Genomic Transformers Actually Learning?
- mRNABench and the Future of AI in Biology: Why Domain Knowledge Wins
- OncoGAN Creates Synthetic Cancer Genomes, Opening New Paths for Privacy-Preserving Precision Oncology
- Readable Rules, Testable Models: A New Grammar for Virtual Cells
- Multimodal CustOmics: Fusing Pathology Images and Tumor Genomics for Next-Gen Cancer Diagnostics
- Beyond Perturbation Simulations: PDGrapher Shows a Faster Way to Identify Actionable Targets
- Can AI design epigenetic anti-aging strategies?
- What happens when physicians use GPT-4 for diagnosis
- Can generative AI predict emergent phenomena?
- DeepSomatic and the question of how AI learns from itself
- Toward Mechanism-Centric Interpretability in Genomic Machine Learning
- From AlphaEvolve to DeepEvolve: What We’re Learning About Machine-Led Scientific Discovery
- Kosmos and the Culture of Discovery
- From Embeddings to Insight
- From Prediction to Explanation: How BIOREASON Reframes Genomic AI as a Reasoning Problem
- AI Models Need Better Truth—Platinum Pedigree Shows How
- From Evolutionary Intolerance to Clinical Insight: What popEVE Teaches Us About Missense Variants
- Interpretable Latent Spaces, Messy Biology: What AUTOENCODIX Teaches Us About Autoencoders in the Wild
- The Gene Ontology Knowledgebase in 2026
Why it matters
Interpretability is not a transparency feature; it’s a scientific claim about correspondence between computation and biology.
And like any scientific claim, it must be testable, falsifiable, and revised in light of evidence.
Comments
Powered by WP LinkPress