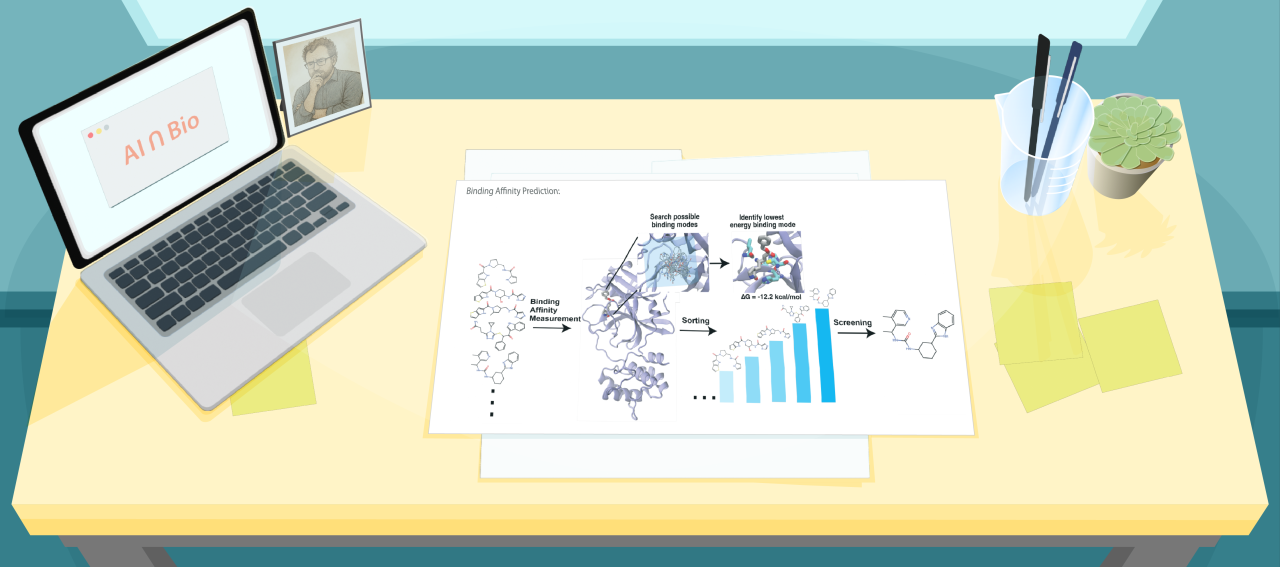
In molecular design, we often prioritize what’s measurable over what’s meaningful.
For decades, binding affinity has served as a cornerstone of early-stage drug discovery, not because it captures biological function in full, but because it’s one of the few properties we can quantify systematically and optimize across large libraries.
Now, as AI models generate binders faster than we can validate them, we must ask: What exactly are we optimizing for? And what datasets are we training on?
What we know:
- Strong binding doesn’t guarantee efficacy
- Residence time and conformational flexibility can matter more than affinity
- Cellular context — target expression, pathway crosstalk, and off-target interactions — often dictates outcome in clinical applications
Yet much of the public data — and many AI training sets — still orbit around Kd, IC₅₀, and docking scores. These are abundant and easy to label, but they capture only a narrow slice of pharmacological reality (and we’re not even accounting for the fact that these measurements are highly dependent on the specific conditions- buffer, temperature, etc).
If we train models on what’s easy to measure, we shouldn’t be surprised when they generate molecules that impress in silico — and disappoint in vivo.
The problem isn’t that binding doesn’t matter. It does. The problem is that binding isn’t biology.

More in this series
- ChatNT: The future of biological assistants—or a mirage in a lab coat?
- GET: A Foundation Model for Transcription, Still Between Promise and Proof
- X-Atlas/Orion: Your Model is Only as Good as Your Training Data
- From Better Models to Better Questions: A Pathology AI Rethink
- The Model Isn’t the Magic: How Cytoland shows that domain expertise—not just deep learning—is what makes AI in biology work.
- Boltz-2: How much can 3D structure really tell us about molecular binding energetics?
- Investigating the volume and diversity of data needed for generalizable antibody–antigen ΔΔG prediction
- Beyond Binding: Rethinking Drug Design in the Age of AI and Structural Biology
- Testing the Physics Beneath the Predictions Beyond RMSD: What AlphaFold3 Really Understands
- Hype, Hurdles, and Hepatotoxicity: A Bold Step for AI-Designed Drugs, But Still Miles to Go
- When Complexity Misleads
- What Are Genomic Transformers Actually Learning?
- mRNABench and the Future of AI in Biology: Why Domain Knowledge Wins
- OncoGAN Creates Synthetic Cancer Genomes, Opening New Paths for Privacy-Preserving Precision Oncology
- Readable Rules, Testable Models: A New Grammar for Virtual Cells
- Multimodal CustOmics: Fusing Pathology Images and Tumor Genomics for Next-Gen Cancer Diagnostics
- Beyond Perturbation Simulations: PDGrapher Shows a Faster Way to Identify Actionable Targets
- Can AI design epigenetic anti-aging strategies?
- What happens when physicians use GPT-4 for diagnosis
- Can generative AI predict emergent phenomena?
- DeepSomatic and the question of how AI learns from itself
- Toward Mechanism-Centric Interpretability in Genomic Machine Learning
- From AlphaEvolve to DeepEvolve: What We’re Learning About Machine-Led Scientific Discovery
- Kosmos and the Culture of Discovery
- From Embeddings to Insight
- From Prediction to Explanation: How BIOREASON Reframes Genomic AI as a Reasoning Problem
- AI Models Need Better Truth—Platinum Pedigree Shows How
- From Evolutionary Intolerance to Clinical Insight: What popEVE Teaches Us About Missense Variants
- Interpretable Latent Spaces, Messy Biology: What AUTOENCODIX Teaches Us About Autoencoders in the Wild
- The Gene Ontology Knowledgebase in 2026
Toward More Meaningful Models
To do better, we’ll need to:
- Incorporate multi-parametric data: kinetics, permeability, metabolism, toxicity, immune activation
- Train models to include mechanism and uncertainty, not just affinity
- Elevate datasets that link structure to systems, not just structure to scores
The best work ahead won’t just generate molecules; it will surface better models about how they work, and where they fail in the journey from discovery to clinic.
Comments
Powered by WP LinkPress